A board member asks a simple question: of last quarter's inbound demo requests, how many got a human reply within an hour? The CRO knows the answer should take a minute. It takes three people and two days. Marketing exports form fills, SDR managers pull their queues, someone merges duplicate accounts by hand, and the number that finally reaches the board arrives with a footnote about data quality.
That company does not have a reporting problem. It has a maturity problem. The question is unanswerable because no event in the lead's life was ever written as a timestamp against one canonical record. A better dashboard will not fix that, and neither will a fourth enrichment tool. What fixes it is knowing which layer of the revenue engine is missing and building that layer first.
Most maturity models describe stages with adjectives: nascent, developing, advanced, optimized. You cannot audit an adjective. Two leaders will score the same company two stages apart, and neither score tells anyone what to build on Monday. The organizational side of the market has moved fast. Gartner predicted in 2021 that 75% of the highest-growth companies would deploy a RevOps model by 2025. Adopting the org chart is not the same as maturing the systems underneath it, though. Plenty of teams now have a Head of RevOps sitting on top of a stack that still cannot tell them how many accounts they have.
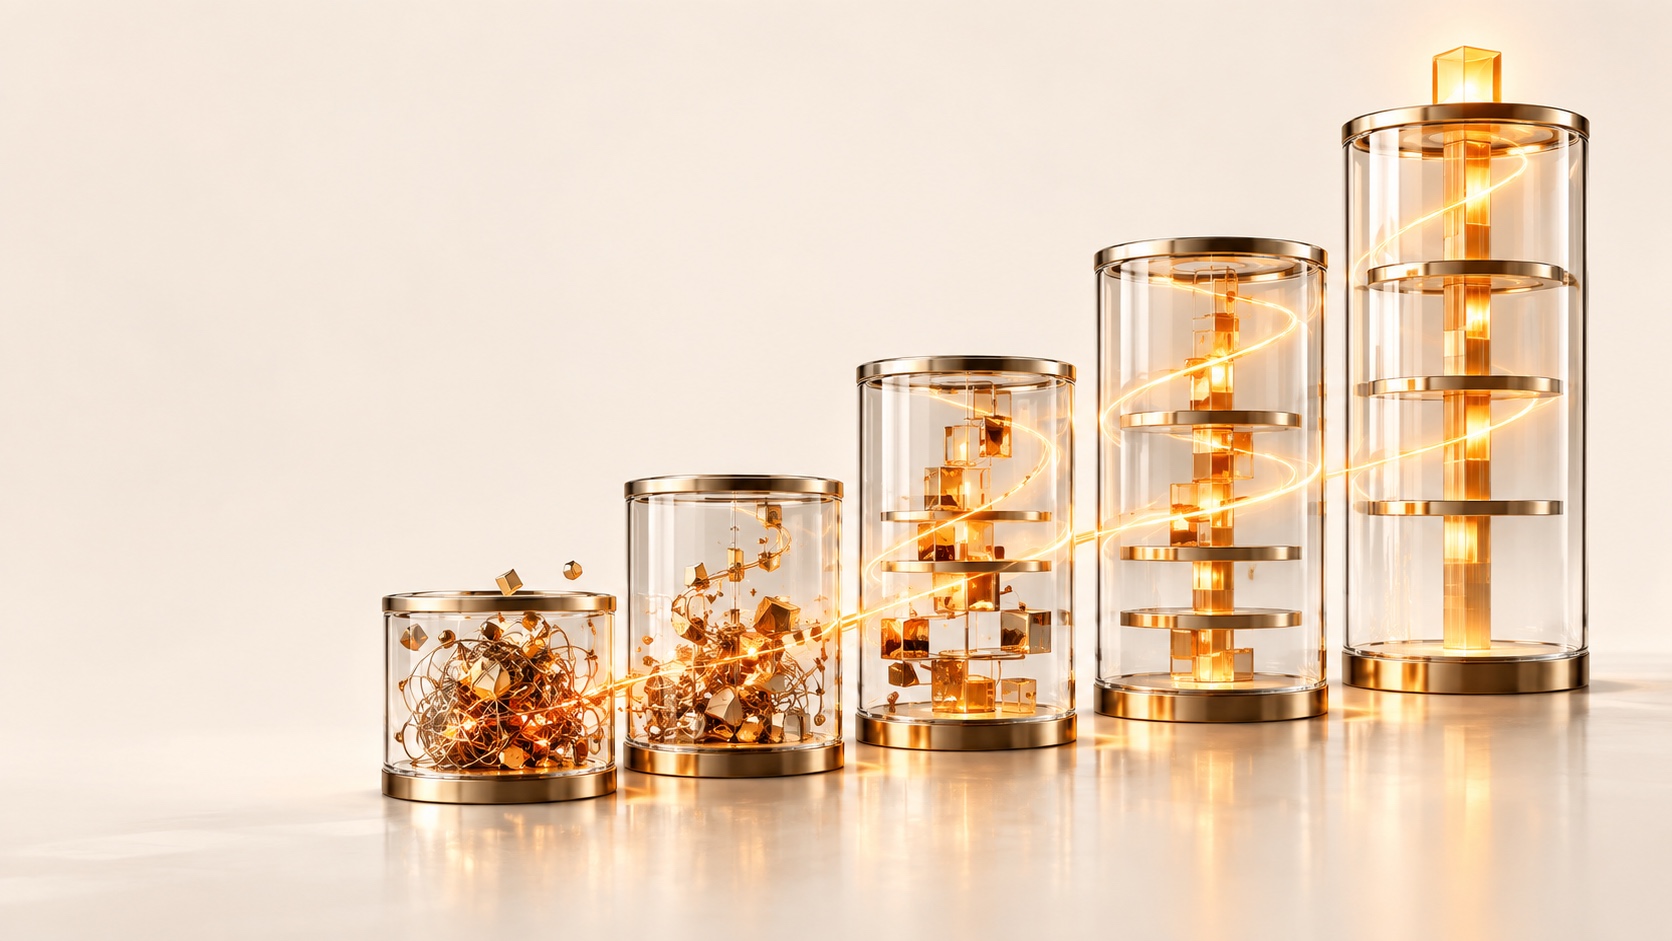
The model below works differently. Each stage is defined by a specific, nameable failure that the stage has eliminated, and each transition is a specific system you build. It is the vocabulary behind our diagnose-before-you-build engagement, and it extends the forward-deployed engineering model for revenue teams into a map of where the work actually goes. The rule that makes it useful: your stage is set by the worst failure you still tolerate, not by the best tool you own.
Where it breaks
Every stage transition has one failure that blocks it. They show up in a predictable order because each one sits on top of the one before it.
Stage 1 failure: three versions of every account
Web forms create accounts. List imports create accounts. Reps create accounts by hand when search fails them, and every enrichment tool writes its own version back. Without an enforced matching key, usually the normalized web domain for accounts and the lowercased email for contacts, the CRM keeps multiplying the same company. The damage spreads downstream: round-robin routing assigns the same buyer to two reps, attribution counts one deal twice, and pipeline reports disagree with finance. Validity's 2026 survey found that nearly a third of teams spend six or more hours a week just fixing and reconciling data. That is a full working day every week spent standing still.
Stage 2 failure: handoffs that live in someone's inbox
At Stage 2 the tools are connected, but the transfer of ownership is not. Marketing qualifies a lead and tells the SDR team in Slack. The SDR books a meeting and the AE finds out from a calendar invite. None of those transitions is written as an event with an owner and a timestamp, so nobody can measure the gap between them. The cost of that gap is well documented. In the Harvard Business Review study of 2,241 US companies (Oldroyd, McElheran and Elkington, 2011), the average first response to a web lead took 42 hours, and firms that responded within an hour were nearly seven times as likely to qualify the lead as firms that waited even one hour longer.
Stage 3 failure: signals that land in a report instead of a queue
Stage 3 teams have clean records and timestamped handoffs, so their reporting finally works. The failure here is subtler. Funding announcements, hiring spikes, pricing-page visits and product usage drops are captured, and then they appear in a dashboard someone reviews on Monday. A signal without a route and an owner is a historical fact, not a trigger. By the time the weekly review happens, the action window for most buying signals has already closed.
Stage 4 failure: automation that fails silently
Stage 4 is where teams wire Clay, n8n or Zapier, and the CRM into real workflows. The failure mode is automation nobody watches. An enrichment provider renames a field, a sync job times out halfway through a batch, a retry loop writes the same task forty times, and the first person to notice is a rep asking why their queue is empty. Gartner's 2023 martech survey found marketers using only a third of their stack's capability, down from 58% in 2020. More tools did not produce more capability, because nobody owned the layer between them.
Stage 5 failure: autonomy on data nobody trusts
The newest failure is agents acting on bad inputs. Validity's 2026 report found that nearly 78% of C-suite respondents had acted on an AI recommendation they later suspected was wrong, and only 21% of marketers described their CRM data as very well prepared to support AI. An autonomous agent does not fix a Stage 1 data layer. It scales it.
Reference architecture
Here are the five stages as layers of one architecture. Each box names what the stack looks like at that stage, the data contract that is missing, and the exit test: one question you should be able to answer from the system, without a spreadsheet, before you move on.
What the stack looks like: The CRM is a contact list. Pipeline lives in spreadsheets, forecasts in the CRO's head, and ownership in whoever touched the record last.
Missing contract: A canonical record. There is no enforced matching key for accounts or contacts, and no required fields at stage gates.
Exit test: How many active accounts do we have, and who owns each one?
What the stack looks like: A CRM plus a growing set of point tools joined by native syncs and one-off zaps. Records are mostly clean. People move work between functions by message.
Missing contract: Handoff events. Every ownership change should write an event with the owner, a timestamp and an SLA.
Exit test: What was our median time from form fill to first human touch last month, by source?
What the stack looks like: Lifecycle events are timestamped and reporting is trusted. A named person owns data quality. Signals are captured and reviewed.
Missing contract: Signal routing. Each signal type needs an owner, an action window and a destination queue.
Exit test: For last week's highest-intent signals, how many reached an owner inside their action window?
What the stack looks like: Workflows run across tools with an orchestration layer that owns state, retries and logging. Systems such as lead routing and handoff management run continuously.
Missing contract: Observability. Every automated action needs a log entry, an error path and an alert when it fails or stops running.
Exit test: Which automations failed this week, and what did each failure touch?
What the stack looks like: Systems detect, decide within guardrails, act and log. People handle exceptions, approvals and strategy instead of moving records around.
Missing contract: Proof. Each system is tested against historical cases before it acts, and every action it takes is reversible or gated by a human.
Exit test: What did our systems do on their own yesterday, and what share of it would a senior operator have done the same way?
If you want to score yourself quickly, the logic fits in a few lines. The thresholds are suggested starting points, not industry benchmarks, so tune them to your motion:
stage = 1
if duplicate_account_rate < 2% and required_fields_enforced:      stage = 2
if stage == 2 and handoffs_timestamped and sla_breach_rate_known: stage = 3
if stage == 3 and signals_routed_within_action_window > 80%:      stage = 4
if stage == 4 and silent_failures_detected_same_day:             stage = 5
# a single failed check caps the stage, whatever tools you own
Build sequence
Moving up one stage is a build, not a purchase. The sequence below is the order we use because each step produces the data the next step depends on.
Score your current stage from exports, not opinions
Pull account, contact, lead and opportunity exports, read-only. Run the five exit tests against the data itself. Wherever a question needs a spreadsheet to answer, that is your ceiling.
Establish the canonical record
Choose matching keys (normalized domain for accounts, lowercased email for contacts), merge the existing duplicates, and block new ones at every entry point: forms, imports, manual creation and enrichment write-backs. Make stage-gate fields required.
Timestamp every handoff
Model each ownership change as an event with an owner, a timestamp and an SLA. Alert on breaches automatically. This is where speed-to-lead stops being a slogan and becomes a number you can trend.
Route signals by action window
List your signal types, give each one an owner and a window, and send them to queues instead of dashboards. A signal that arrives after its window closes should be logged as a miss, not quietly dropped.
Put an orchestration layer in charge of state
Move retries, error handling and logging out of individual zaps and into one layer that knows the state of every record in flight. Point tools keep doing what they are good at, while the orchestration layer owns what happens when they fail.
Test on your own history before granting autonomy
Before any system acts on its own, run it against around twenty of your own past cases, labeled by your team. If it does not match what a senior operator would have done at a high enough rate, it does not go live.
Build vs. buy: trade-offs
Every transition can be handled three ways. None of them is right at every stage, and the most expensive mistake is using a Stage 4 approach to solve a Stage 1 problem.
| Approach | Best fit | Cost of ownership | Failure risk |
|---|---|---|---|
| Native CRM configuration | Stage 1 to 2: matching rules, required fields, validation, basic assignment | Low. An admin can own it, but it fragments as rules pile up across objects | Rules drift out of date after reorgs, and nobody notices until reports disagree |
| Point tools joined by iPaaS or workflow tools | Stage 2 to 3: enrichment, routing, handoff alerts across a handful of tools | Medium. Licenses are cheap, but debugging time grows with every tool you add | Silent failures between tools, with no single owner of state |
| Embedded, forward-deployed build | Stage 3 to 5: orchestration, signal routing, tested autonomy inside your existing stack | Higher up front, and it is scoped by a diagnosis rather than open-ended | Scope creep if the engagement starts without a fixed-scope diagnosis |
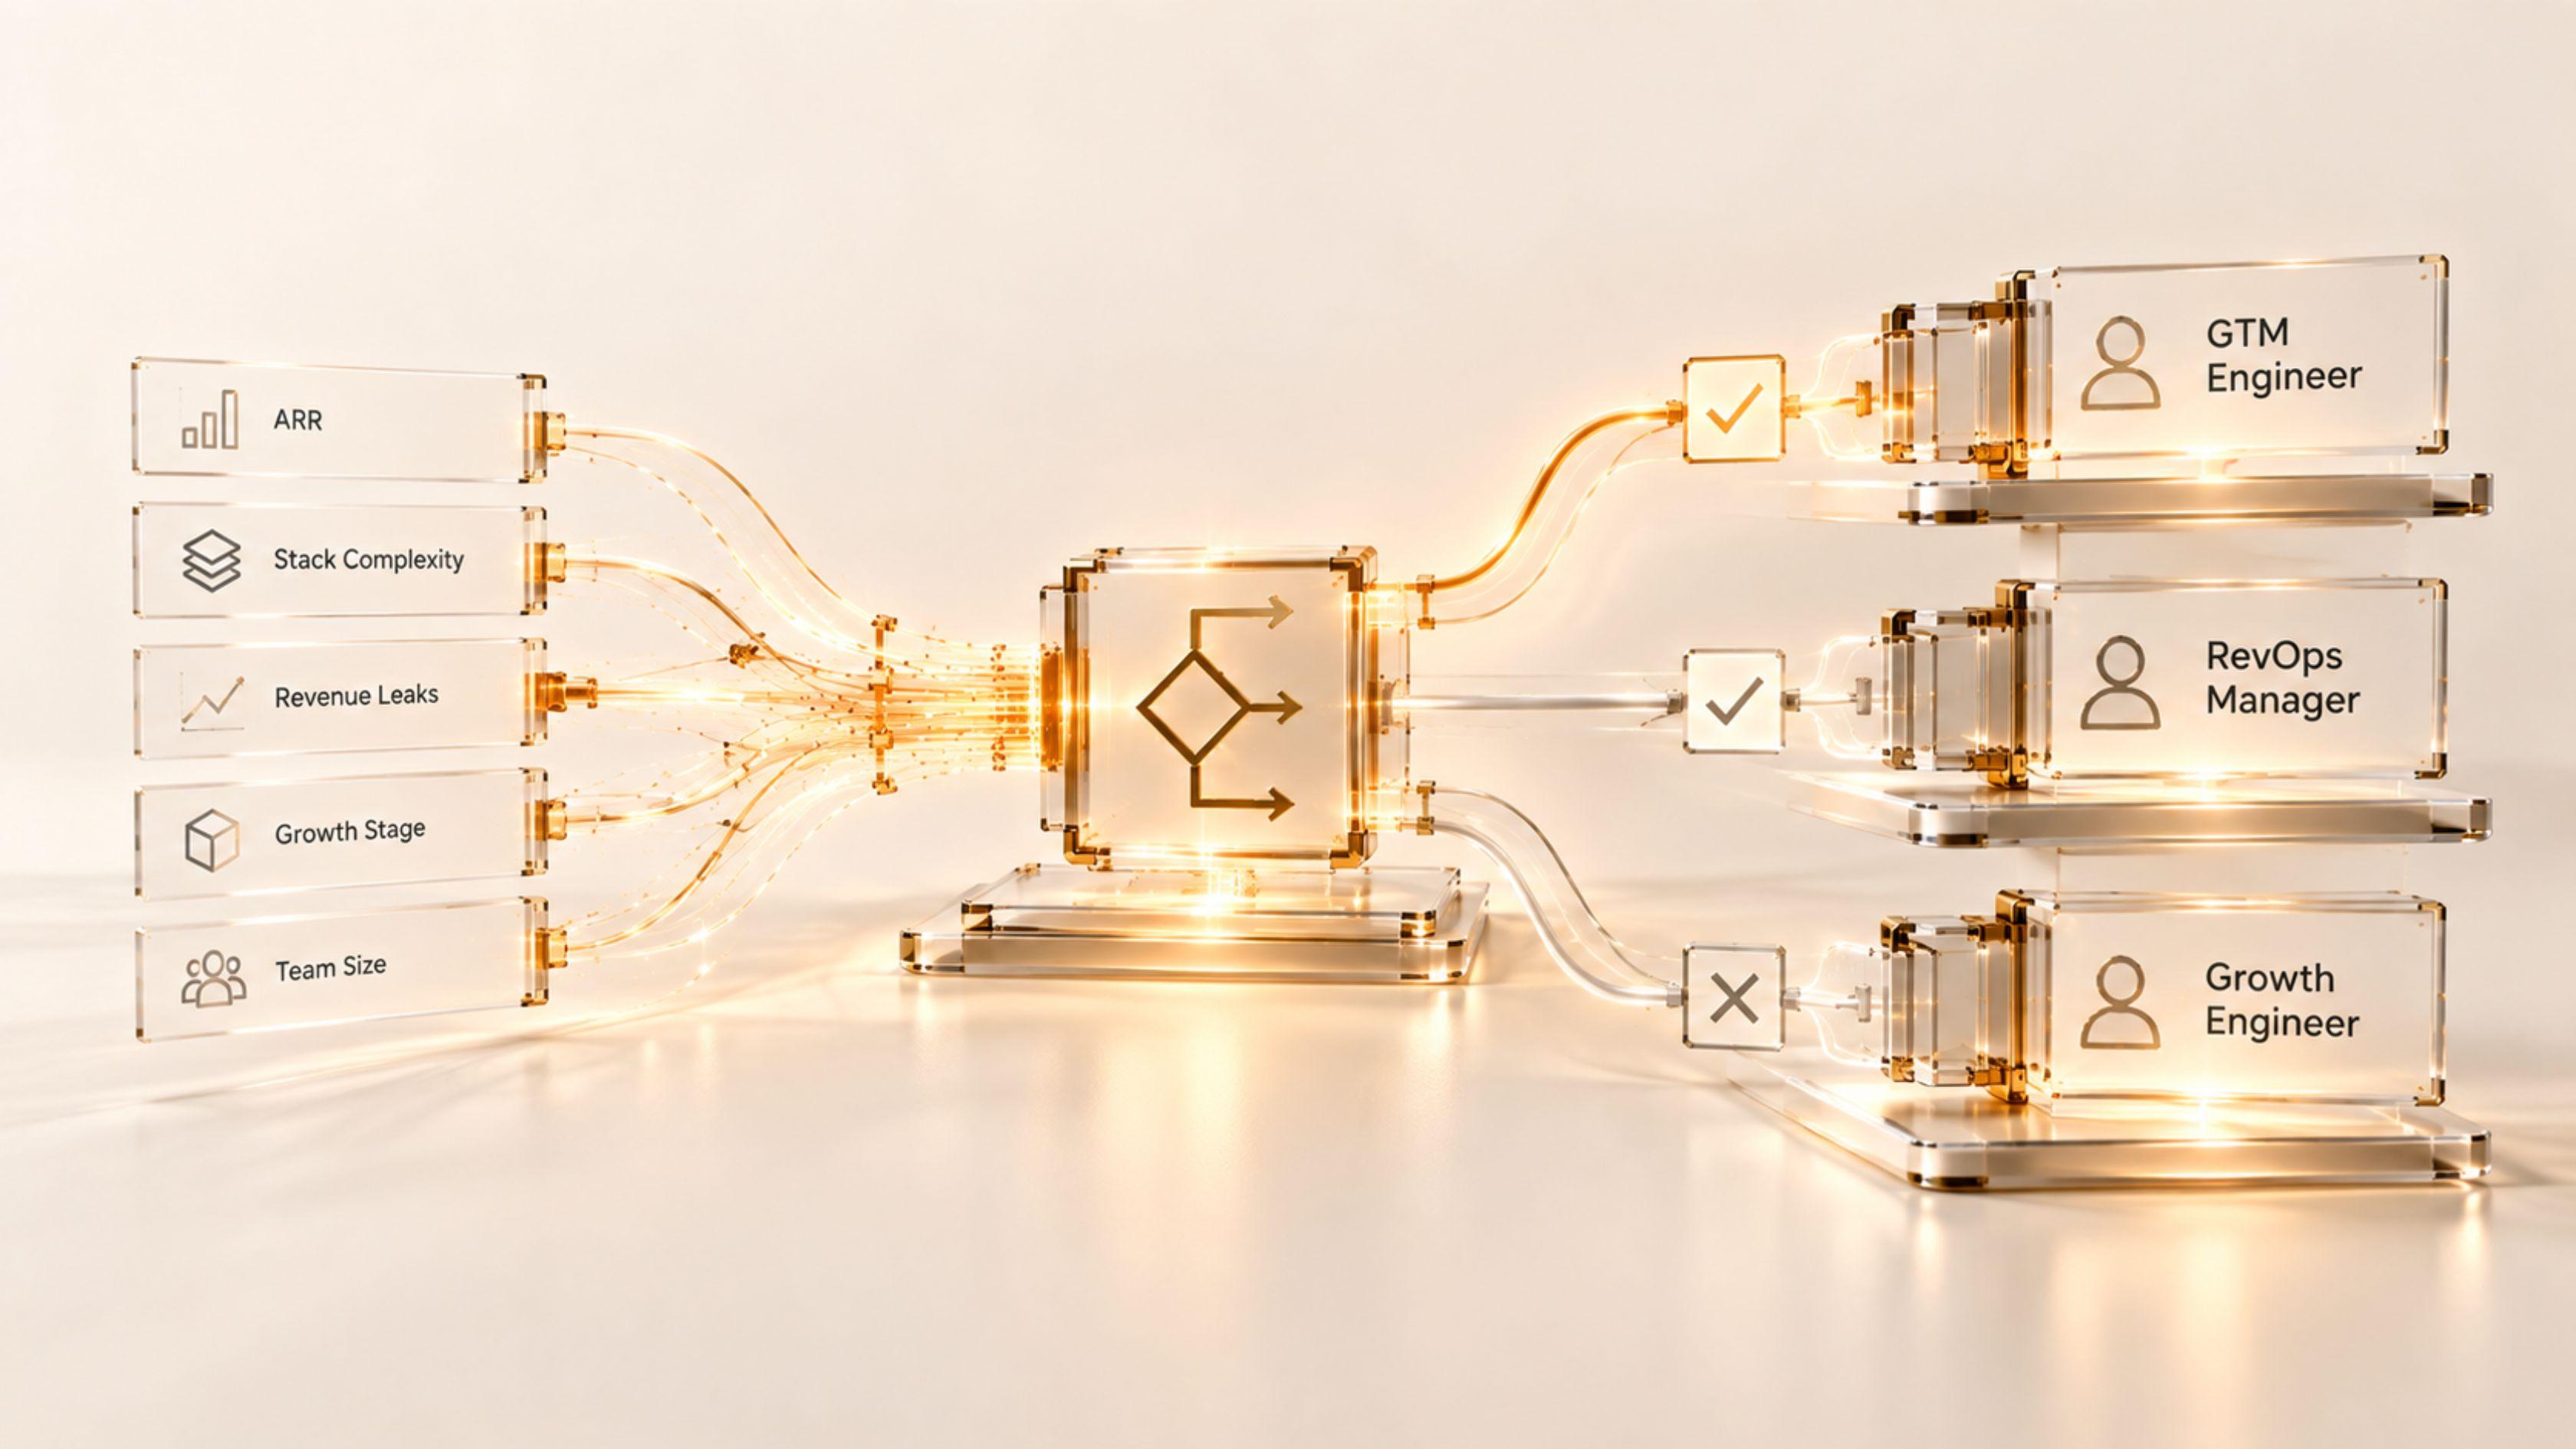
A common and costly pattern is a Stage 1 or 2 team buying Stage 4 tooling and wondering why nothing improved. Gartner's utilization data points in the same direction. If you are still deciding who should own this work, the GTM engineer vs. RevOps manager vs. growth engineer decision tree maps the hire to the stage.
Running it in production
Maturity is not a milestone you pass once. Every reorg, new tool and new segment pulls a stack back down a stage unless someone is watching the right numbers.
Track one exit metric per stage every week: duplicate account rate, handoff SLA breach rate, signal-to-action time, and the count of automation failures found by an alert instead of by a rep. If any of them moves the wrong way for two weeks running, you have slipped a stage, whatever the dashboard says.
Every automated action writes a log entry and has a way back. Anything expensive or hard to reverse, like pricing, contract terms or messages to existing customers, stays behind a human approval gate at every stage. Our own bar is simple: a system ships at 85 percent on the client's historical cases, or it does not ship.
Boards do not need the architecture. They need four facts on one slide: the current stage, the worst failure you still tolerate, what that failure costs in dollars, and the one build that removes it. That turns a RevOps roadmap into a capital-allocation decision leadership can actually make.
Where this fits in the system
Each stage transition maps to specific systems we build. Moving from Stage 2 to 3 is the work of Speed-to-Lead and the Handoff Orchestrator, which turn handoffs into timestamped, SLA-bound events. Holding Stage 3 depends on the Pipeline Hygiene Sentinel, because instrumented data decays without continuous enforcement. Moving to Stage 4 is where the Signal-Based Outbound Engine routes signals by action window. Stage 5 is where systems like the Churn Signal Watchtower and the Board Report Engine run on their own with a person on the exceptions. The full map lives on the systems page.
The model also explains why embedding engineers only works with a bounded scope. As we argued in what Palantir's forward-deployed model gets right and wrong for revenue teams, forward-deployed work without a fixed diagnosis turns into open-ended consulting. The maturity stage is that diagnosis. It tells you which layer to build next, and it tells you when you are finished.
Future posts in this series use the same vocabulary. When we write about identity resolution, orchestration layers or agent governance, the stage tells you whether the piece applies to you yet.
Sources: Validity, State of CRM Data Management 2026 (n=500 marketing professionals, August 2026). Salesforce, State of Sales, 5th edition (n=7,775 sales professionals, December 2022). Gartner, 2023 Marketing Technology Survey. Gartner, press release, May 17, 2021, on RevOps adoption by 2025. Oldroyd, McElheran and Elkington, "The Short Life of Online Sales Leads," Harvard Business Review, March 2011.