A Series B company hires its first GTM engineer. She is good. In fourteen months she ships lead routing, an enrichment waterfall, a Slack alert for high-intent accounts and a nightly job that reconciles product usage into the CRM. Then she takes a better offer. Three weeks later, inbound leads stop getting assigned. It takes the team four days to discover why: the workflow that wrote Lead.OwnerId ran under her personal account on an automation tool, authenticated with her API key, and the key was revoked when IT offboarded her. Nobody else knew that workflow existed, let alone which of the eighty others depended on it.
Down the road, a similar company took the other path and bought a revenue platform with routing, sequencing and scoring built in. Implementation went smoothly. Eleven months later, the platform uses a lead-to-account matching rule that disagrees with the CRM, custom objects never synced, and a RevOps manager spends Fridays exporting CSVs to answer questions the platform was supposed to answer. Neither made a bad hire or bought a bad tool. Both made an architecture decision without realizing it.
Demand for this work is not in question. Bloomberry's 2026 analysis of the same 1,000 postings concluded that GTM engineering and RevOps jobs are, in responsibilities, largely the same job with a heavier emphasis on automation and integration. What remains unsettled is the operating model. Most companies frame it as a hiring question, which hides the two decisions that determine whether the function works. The first is which layers of the revenue stack you need to own versus rent. The second is who holds the state of every automated process, meaning the credentials, the field write-back rules, the retry logic and the logs, when the person who built it is no longer there.
Treat it as a systems problem and the three options become comparable. Build means hiring internally and owning every layer. Buy means licensing a platform and accepting its data model. Embed means bringing in a forward-deployed engineering team that diagnoses first, builds inside your existing stack and hands over systems your team can run. Each one fails in a predictable way, and each failure names the objects that break.
Where it breaks
Every one of these failure modes is architectural, which is why a stronger hire or a better tool rarely fixes it.
Build: the single-maintainer stack
An internal hire moves fast because there is no process in the way. That speed accumulates as undocumented state: workflows created under a personal login, API keys issued to an individual rather than a service account, enrichment columns that write back to CRM fields nobody else knows are managed, and cron schedules that exist only in one tool's UI. The bus factor of the entire revenue engine is one. The US Bureau of Labor Statistics reported in September 2026 that median tenure with the current employer was 3.0 years for workers aged 25 to 34, which is the age band most early GTM engineers fall into. If the system cannot survive one resignation, it is not a system.
Build: hiring into a stack nobody has diagnosed
Bloomberry's data shows postings asking for an average of 4.11 years of experience, with SQL and Python each appearing in 38% of listings. Companies are hiring engineers. Then they point those engineers at a CRM with three versions of every account and no timestamped handoffs, and the first two quarters go to merging duplicates and rebuilding validation rules. Without a diagnosis before the hire, the role is scoped around symptoms, and the engineer spends a year discovering what a read-only audit could have mapped in weeks. We made the longer version of this argument in the diagnose-before-you-build playbook.
Buy: the platform configured to the demo, not your data model
Platforms ship with an opinionated schema. The failure appears at the seams: the vendor's account-matching logic disagrees with your CRM's, custom objects such as Subscription__c or a product-usage table are not part of the sync, bidirectional field mappings overwrite each other, and the platform's routing rules live outside the CRM where your admin cannot audit them. Gartner's 2023 Marketing Technology Survey found marketers using only a third of their stack's capability, down from 58% in 2020.
Buy: assuming the vendor carries the learning
The strongest argument for buying comes from AI. MIT NANDA's 2025 study, based on 150 leader interviews, a survey of 350 employees and 300 public deployments, found that tools purchased from specialized vendors succeeded about 67% of the time, while internal builds succeeded only about a third as often. The same research located the failure in a learning gap: generic tools that do not adapt to an organization's workflows stall. Buying helps when the vendor adapts the tool to your process. It hurts when your process has to bend around the tool, and the configuration work that closes that gap still has to be done by someone.
Embed: engagements without a boundary or a handover
An embedded team can close the gap between build and buy, but it has its own failure mode. Without a fixed-scope diagnosis, embedded work becomes open-ended consulting, as we covered in what Palantir's forward-deployed model gets right and wrong for revenue teams. Without a handover contract, it recreates the single-maintainer problem at the level of a vendor: the logic runs in the provider's accounts and the runbooks live in their heads.
Reference architecture
The decision gets easier when you stop choosing a model for the whole function and choose one per layer. Each box below names the components, example tools (examples, not endorsements), the data contract it hands to the next layer, and which model tends to fit it.
Components: Web forms, product events, enrichment and intent providers, calendar and email activity, billing.
Example tools: Form builders, a product analytics pipeline, enrichment vendors, the billing system.
Contract to the next layer: Every event carries a source, a timestamp and a raw identifier (email, domain or account ID).
Best fit: Buy. Sources are commodities, and building your own enrichment rarely pays.
Components: Matching keys, merge rules, required fields, validation at every entry point, including imports and enrichment write-backs.
Example tools: Native CRM duplicate rules, dedicated dedupe tools, a warehouse model for identity.
Contract to the next layer: One canonical account and contact ID, with a documented rule for how it was resolved.
Best fit: Own it, whether built internally or embedded and handed over. Your matching logic encodes your business, so it cannot be rented.
Components: Routing, SLAs, signal handling, retries, error paths, logging.
Example tools: Workflow tools such as n8n or Make, iPaaS, CRM flows, or custom services.
Contract to the next layer: Every action is idempotent, logged with the record ID, and runs under a service account.
Best fit: Build or embed. This layer holds the state that disappears when people leave, so it must run under company credentials with version-controlled logic.
Components: CRM objects, lifecycle stages, ownership fields, the audit trail.
Example tools: Salesforce, HubSpot.
Contract to the next layer: Stage gates enforced by required fields, and every ownership change written as a timestamped event.
Best fit: Buy the platform, own the configuration.
Components: Sequencing, alerts, AI drafting and summarization, forecasting and reporting outputs.
Example tools: Engagement platforms, conversation intelligence, specialized AI tools.
Contract to the next layer: Actions are reversible or gated by a human, and every one is traceable to the input that triggered it.
Best fit: Buy specialized tools or embed tested systems. The MIT data favors specialized tools over internal builds here, provided someone adapts them to your workflow.
Build sequence
This order works whichever model you choose, and each step produces something testable.
Diagnose the stack read-only
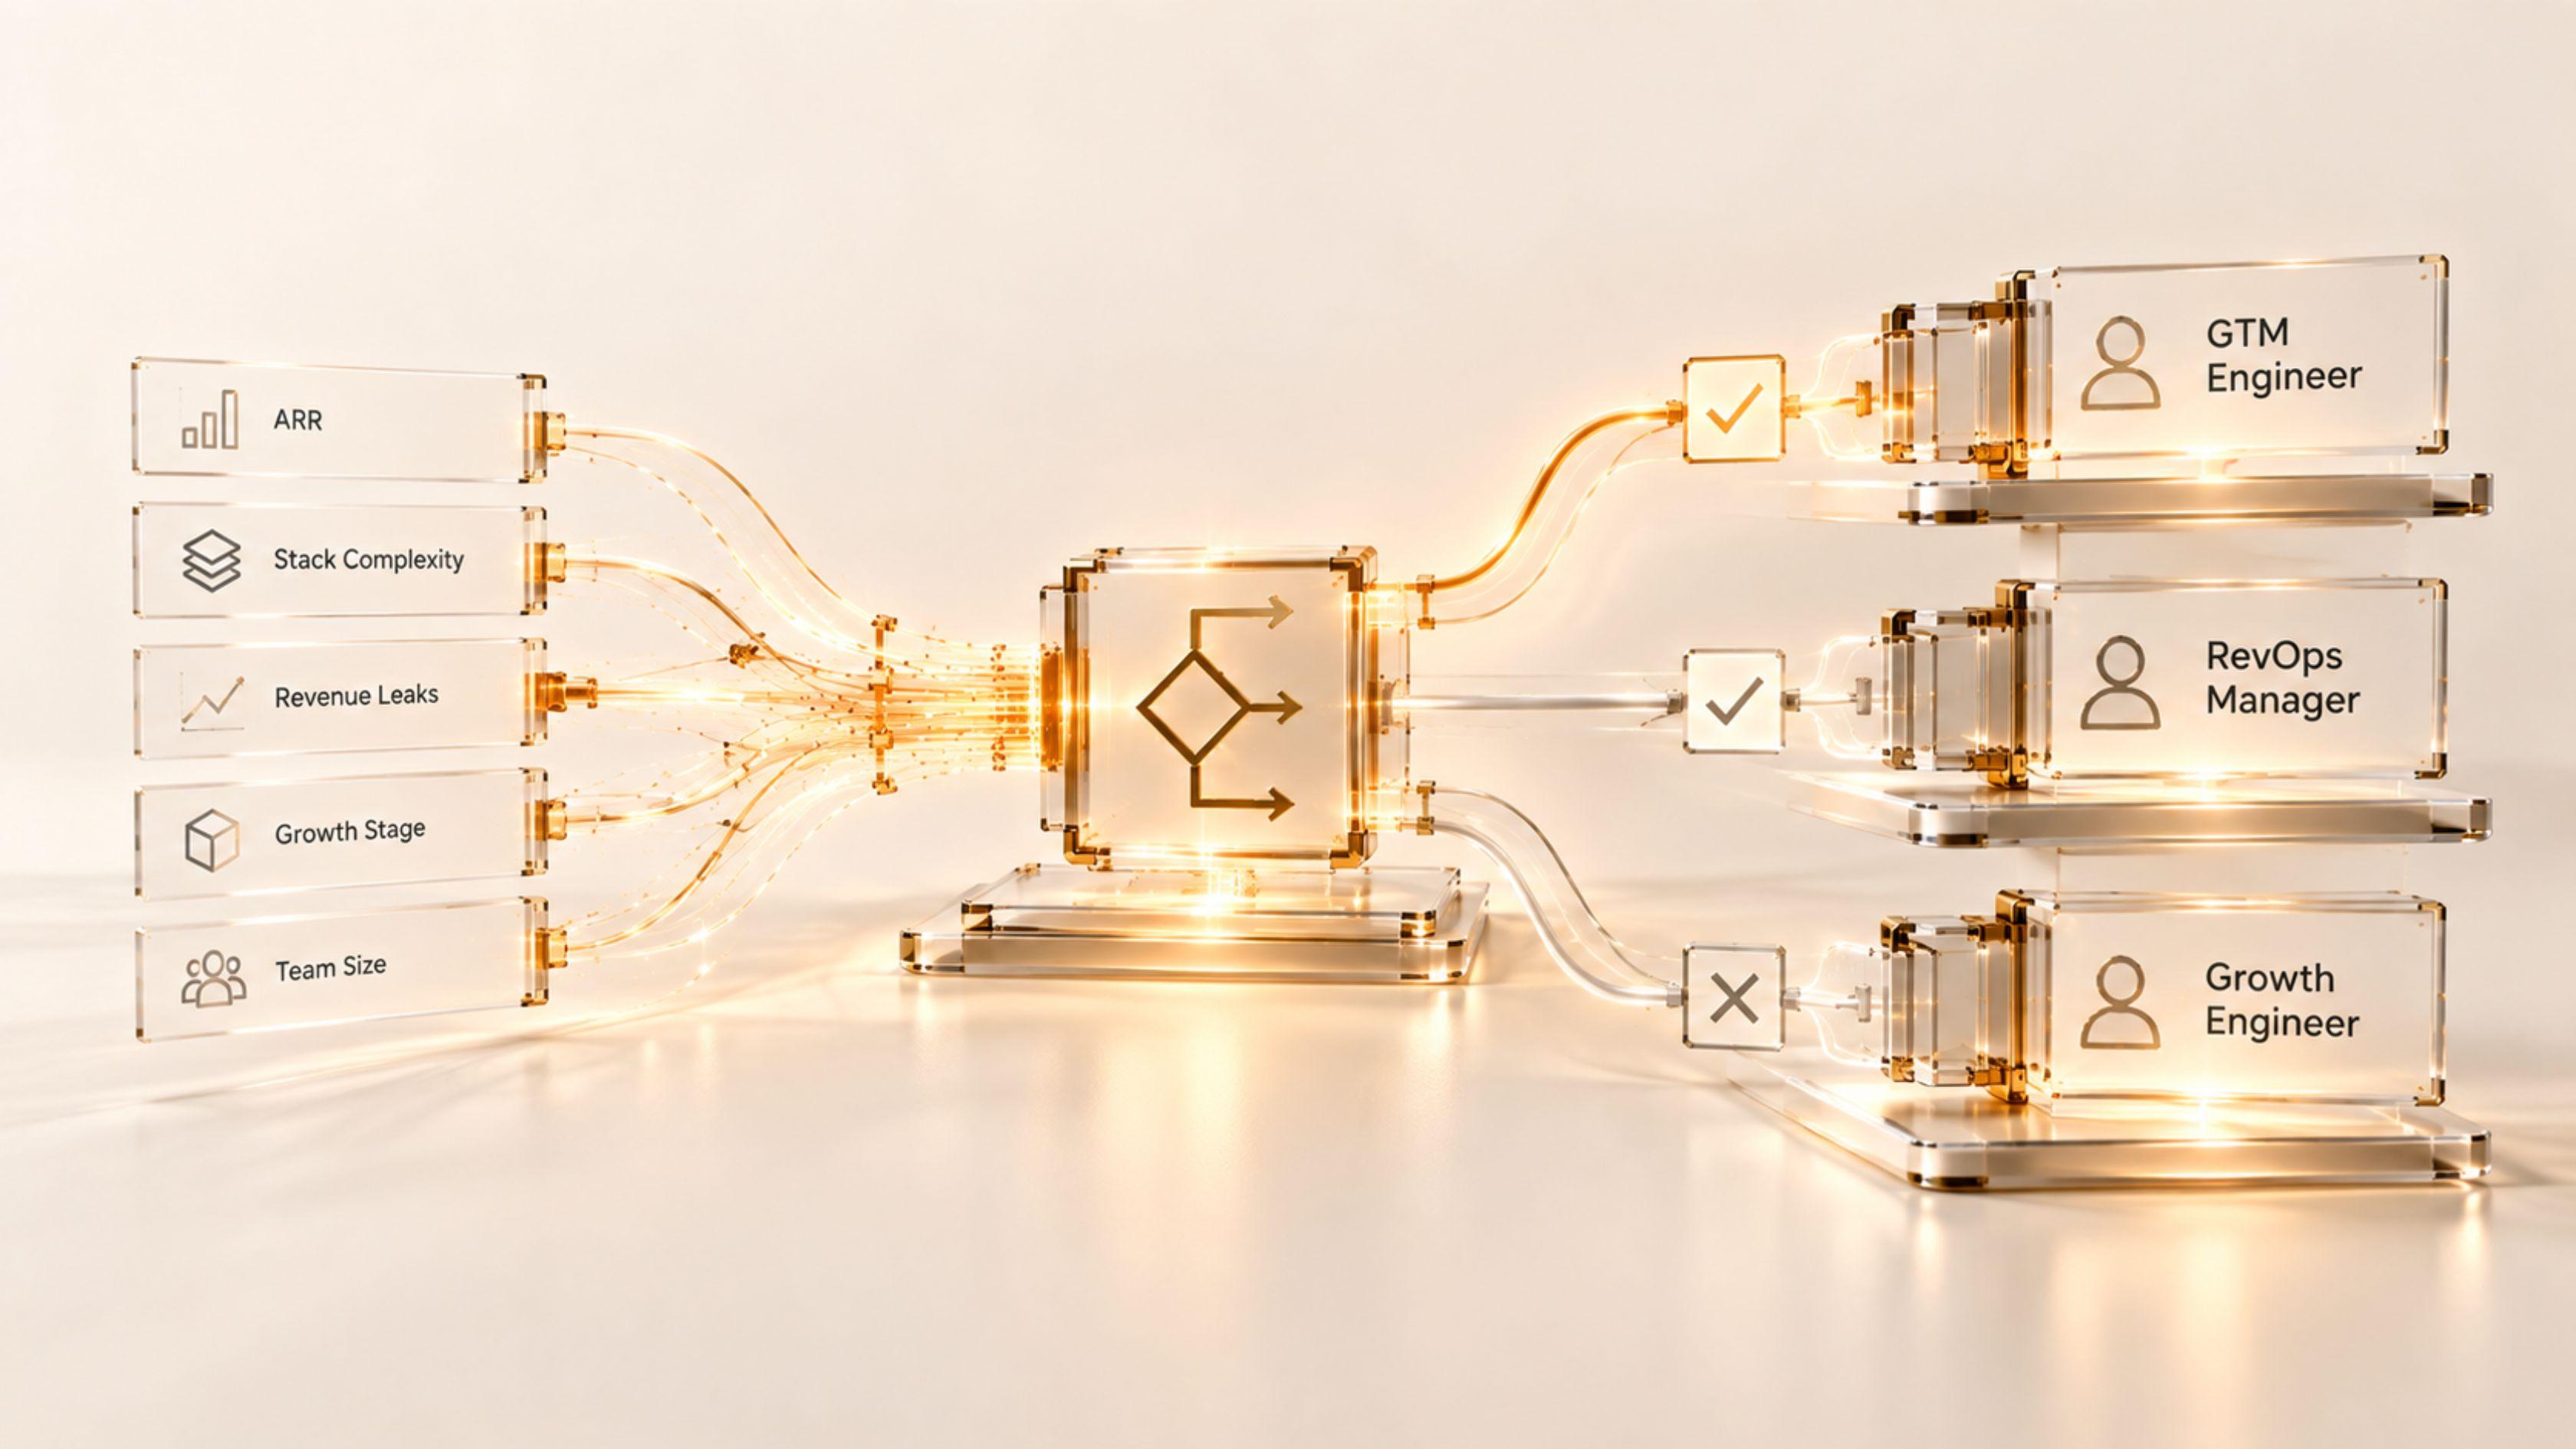
Export accounts, contacts, leads, opportunities and automation inventories. Measure the duplicate rate, the handoff gaps and the share of revenue questions that need a spreadsheet to answer. That places you on the RevOps maturity model and tells you which layer is missing, which in turn tells you what kind of capacity you need. For the org-design side, the GTM engineer vs. RevOps manager vs. growth engineer decision tree maps the hire to the stage.
Inventory every holder of state
List every workflow, integration, scheduled job and API key, and record who owns it and which fields it writes. Anything tied to a personal account goes on a migration list.
Assign a model per layer
Use the reference architecture: buy sources and the system of record, own identity and orchestration, and decide activation by whether a specialized tool fits your workflow without heavy bending.
Model cost and time to first live system
Compare the three paths on the same two numbers: first-year cost and calendar weeks until one system runs in production against your data. The model below shows the shape of the calculation.
Write the handover contract before any work starts
Service accounts instead of personal ones, logic in version control, a runbook per system, alerts routed to a team channel, and a named internal owner. This applies to an internal hire as much as to a vendor.
Test on your own history before go-live
Run each system against around twenty of your own past cases, labeled by your team, before it touches live records. Set the pass bar in advance. Ours is 85 percent agreement with what a senior operator would have done, or the system does not ship.
The cost comparison is simple arithmetic once the inputs are honest. The salary and cost-per-hire inputs below come from the sources cited in this post. Every other value is a placeholder for your own numbers, not a benchmark.
# Illustrative example: replace every assumption with your own inputs
build_year1   = base_salary * (1 + burden_rate) + cost_per_hire + tooling
              # base_salary  = 150,000   (RevGuild 2026 median base)
              # cost_per_hire = 4,700    (SHRM benchmarking, 2022)
              # burden_rate, tooling = your finance team's numbers
build_weeks   = weeks_to_fill + weeks_to_ramp + weeks_to_first_system
buy_year1     = license + implementation + internal_admin_time
buy_weeks     = weeks_to_implement + weeks_to_adapt_to_your_schema
embed_year1   = diagnostic + system_builds + internal_owner_time
embed_weeks   = diagnostic_weeks + weeks_to_first_system
# compare cost per system in production, not cost per head
The last line changes decisions. A hire can look cheaper per year and still cost more per working system once you add the months before the first one ships, and a platform looks cheapest until you price the time needed to adapt it to your schema.
Build vs. buy: trade-offs
None of the three wins everywhere. The table shows where each fits and how each typically fails.
| Model | Best fit | Cost of ownership | Time to first live system | Failure risk |
|---|---|---|---|---|
| Build: hire internally | Companies with a diagnosed stack, a clear roadmap of several systems and a manager who can review technical work | A full salary before anything ships, plus recruiting cost and tooling. Cost per system falls as the roadmap grows | Slowest: time to fill, then ramp, then build | Single-maintainer state, and roles scoped around symptoms when no diagnosis came first |
| Buy: license a platform | Commodity layers such as sources, the system of record and specialized activation tools that fit your process | Predictable licenses, but internal admin and integration time grows with every custom object | Fast for the vendor's use case, slower for yours | A schema mismatch at the seams, and logic living outside your CRM |
| Embed: forward-deployed team | Companies that need systems running inside an existing stack before they can justify or manage a full-time hire | Scoped by a diagnosis and a system count rather than headcount. Requires an internal owner | Fast: the diagnostic finds the first system, which is then tested on your history | Open-ended scope without a fixed diagnosis, and vendor-held state without a handover contract |
In practice the strongest setups are hybrids. A common pattern is to embed to diagnose and ship the first systems, buy for the commodity layers, then hire an internal engineer or operator once there is a running estate worth owning.
Running it in production
The model you choose matters less than whether the function survives month eighteen.
Track the holders of state, not just the outputs. Once a month, review the automation inventory: count workflows running under personal credentials (the target is zero), count jobs with no alert on failure, and count fields written by more than one integration.
Every system needs a documented manual fallback and a kill switch that an operator, not only an engineer, can use. If the routing workflow stops, leads should fall into a monitored default queue rather than into nobody's. Actions that are hard to reverse, like customer messages, pricing and ownership changes on open deals, stay behind human approval whichever model built them.
Present the choice as capital allocation, not headcount. Show each model's first-year cost, its weeks to the first live system and its cost per system in production, alongside the dollar value of the leak that system closes. Boards fund closed leaks more readily than job titles.
Where this fits in the system
The build, buy or embed decision is really a decision about who stands up and runs specific systems. For most companies at $3M to $30M ARR, the first candidates sit where handoffs happen: Speed-to-Lead and the Handoff Orchestrator live in the orchestration layer, the one that most needs owned state and company credentials. The Pipeline Hygiene Sentinel protects the identity and system-of-record layers that every other system depends on, which is why it pays off under any model. Activation-layer systems such as the Signal-Based Outbound Engine only work once the layers beneath them hold. The full map is on the systems page.
This is also where the embed model earns its place in the comparison. It is not an alternative to hiring. Done well, it is the step that makes the hire succeed: a bounded diagnosis, a few systems tested on your own data and running in your accounts, and a handover that turns the next engineer's first quarter into operation rather than archaeology.
Sources: Bloomberry, "I analyzed 1,000 GTM Engineering jobs" (Henley Wing Chiu, updated January 2026). RevGuild, GTM Engineer Salary Market Report 2026 (data from Glozo Talent Intelligence, n=71 roles with disclosed pay, July 2026). MIT NANDA, The GenAI Divide: State of AI in Business 2025 (August 2025, as reported by Fortune). US Bureau of Labor Statistics, Employee Tenure in January 2026 (September 2026). SHRM, "The Real Costs of Recruitment" (April 2022). Gartner, 2023 Marketing Technology Survey.