Illustrative scenario. A VP of Sales at a Series B SaaS company posts a RevOps Manager req after a bad quarter. Leads are sitting untouched for two days, forecast calls keep missing by 30 points, and the board wants an explanation. Six months later, the new hire has cleaned up sixty Salesforce validation rules, rebuilt three dashboards, and inherited forty undocumented Zapier tasks from a departed sales ops contractor, but the lead response time hasn't moved, because nobody diagnosed that the actual break was a missing webhook between the marketing automation platform and Salesforce, not a reporting gap. The company needed an engineer who could build and own a system. It hired an operator who could maintain one. The title was wrong for the problem, and nobody had written down what the problem actually was before the req went live.
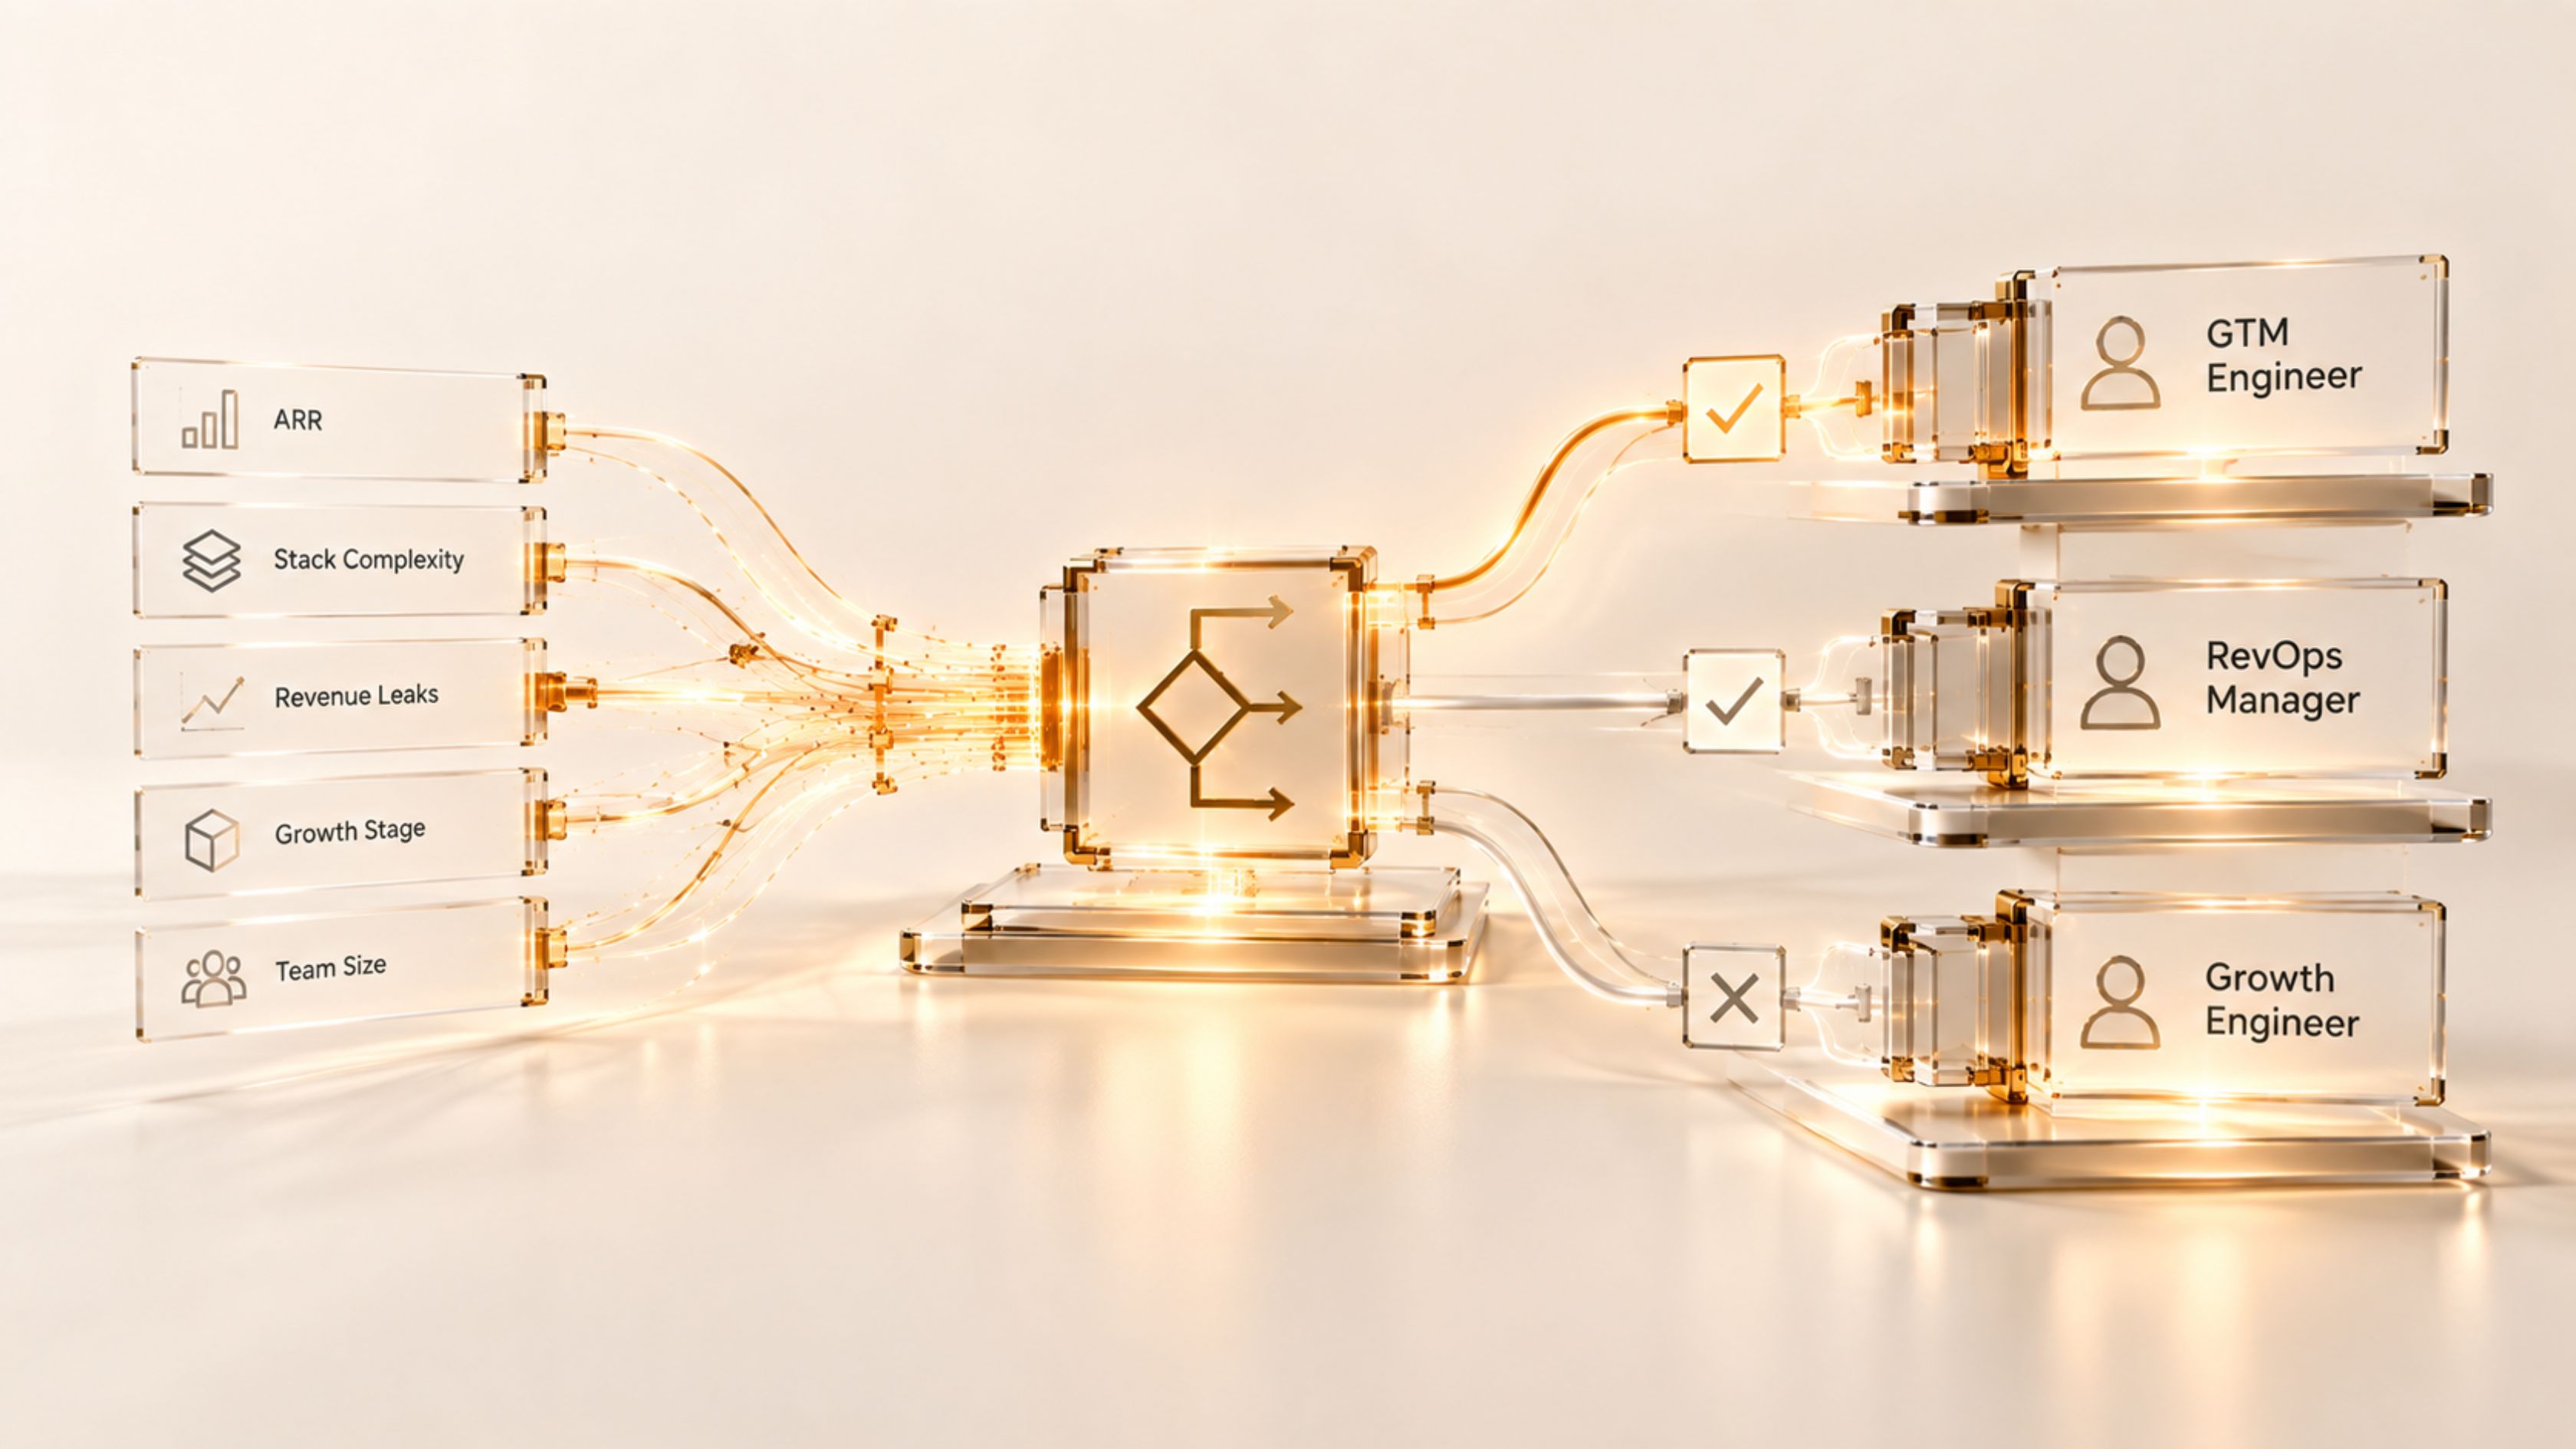
This is not a people problem or a tooling problem: it is a systems architecture problem wearing a job description. GTM Engineer, RevOps Manager, and Growth Engineer are not interchangeable titles for the same function; they map to different layers of the revenue stack, different failure modes, and different cost-of-ownership curves. Hiring the wrong one doesn't just waste a headcount budget line: it leaves the actual break in place while a capable person burns a year working around it. Before you write the req, you need a decision tree, not a title preference.
Where it breaks
Hiring a RevOps Manager to fix an engineering problem
RevOps Managers are excellent at process design, field governance, and reporting logic inside the tools you already own: Salesforce, HubSpot, Outreach, native workflow builders. What they are not equipped to do, in most job descriptions, is write and maintain custom API integrations, build event-driven triggers across systems that don't natively talk to each other, or debug a broken webhook payload at 11pm. When the actual failure is a missing lead.routed event between your form-fill tool and your CRM, a RevOps Manager will build a workaround inside the CRM: a report, a manual queue, a Slack alert someone has to click, because that is the toolkit they have. The symptom improves slightly. The root cause, an unbuilt speed-to-lead system, stays unbuilt.
Hiring a GTM Engineer before there's a stack worth engineering
The inverse failure is just as common. A seed-stage company with 400 CRM records and two sales reps hires a GTM Engineer expecting them to build custom orchestration logic across systems that barely have data in them yet. There's no signal volume to build a Signal-Based Outbound Engine against, no handoff cadence complex enough to justify an orchestrator, and no historical pipeline data to train a forecast model on. The engineer spends the first two quarters doing data entry cleanup and CRM administration, work a RevOps generalist would have done for less, faster, and without the opportunity cost of an engineer's salary sitting idle.
Hiring a Growth Engineer and routing revenue-critical work through them
Growth Engineers are typically product- and experimentation-oriented: built to ship landing pages, run activation loops, and instrument product analytics events. When a company hands them ownership of sales handoff logic or churn signal detection, the work usually gets built as a one-off script rather than a monitored system: no owner for the sync job when it breaks, no alerting when the trigger silently stops firing, no fallback when the source API changes its schema. Growth Engineers are frequently strong builders, but revenue-critical infrastructure needs an owner accountable to sales and CS leadership, not to a growth backlog.
Treating the decision as permanent instead of staged
The most expensive anti-pattern isn't picking the wrong title: it's assuming the first hire is the last hire. A company that needs a RevOps Manager at $3M ARR to build field governance and a GTM Engineer at $8M ARR to build Handoff Orchestrator logic is not making two separate mistakes if it hires both in sequence. It's making a mistake only if it hires the second role before the first one's foundation (clean fields, defined stages, a documented system of record) is in place for the engineer to build on.
Reference architecture: match the role to the layer that's broken
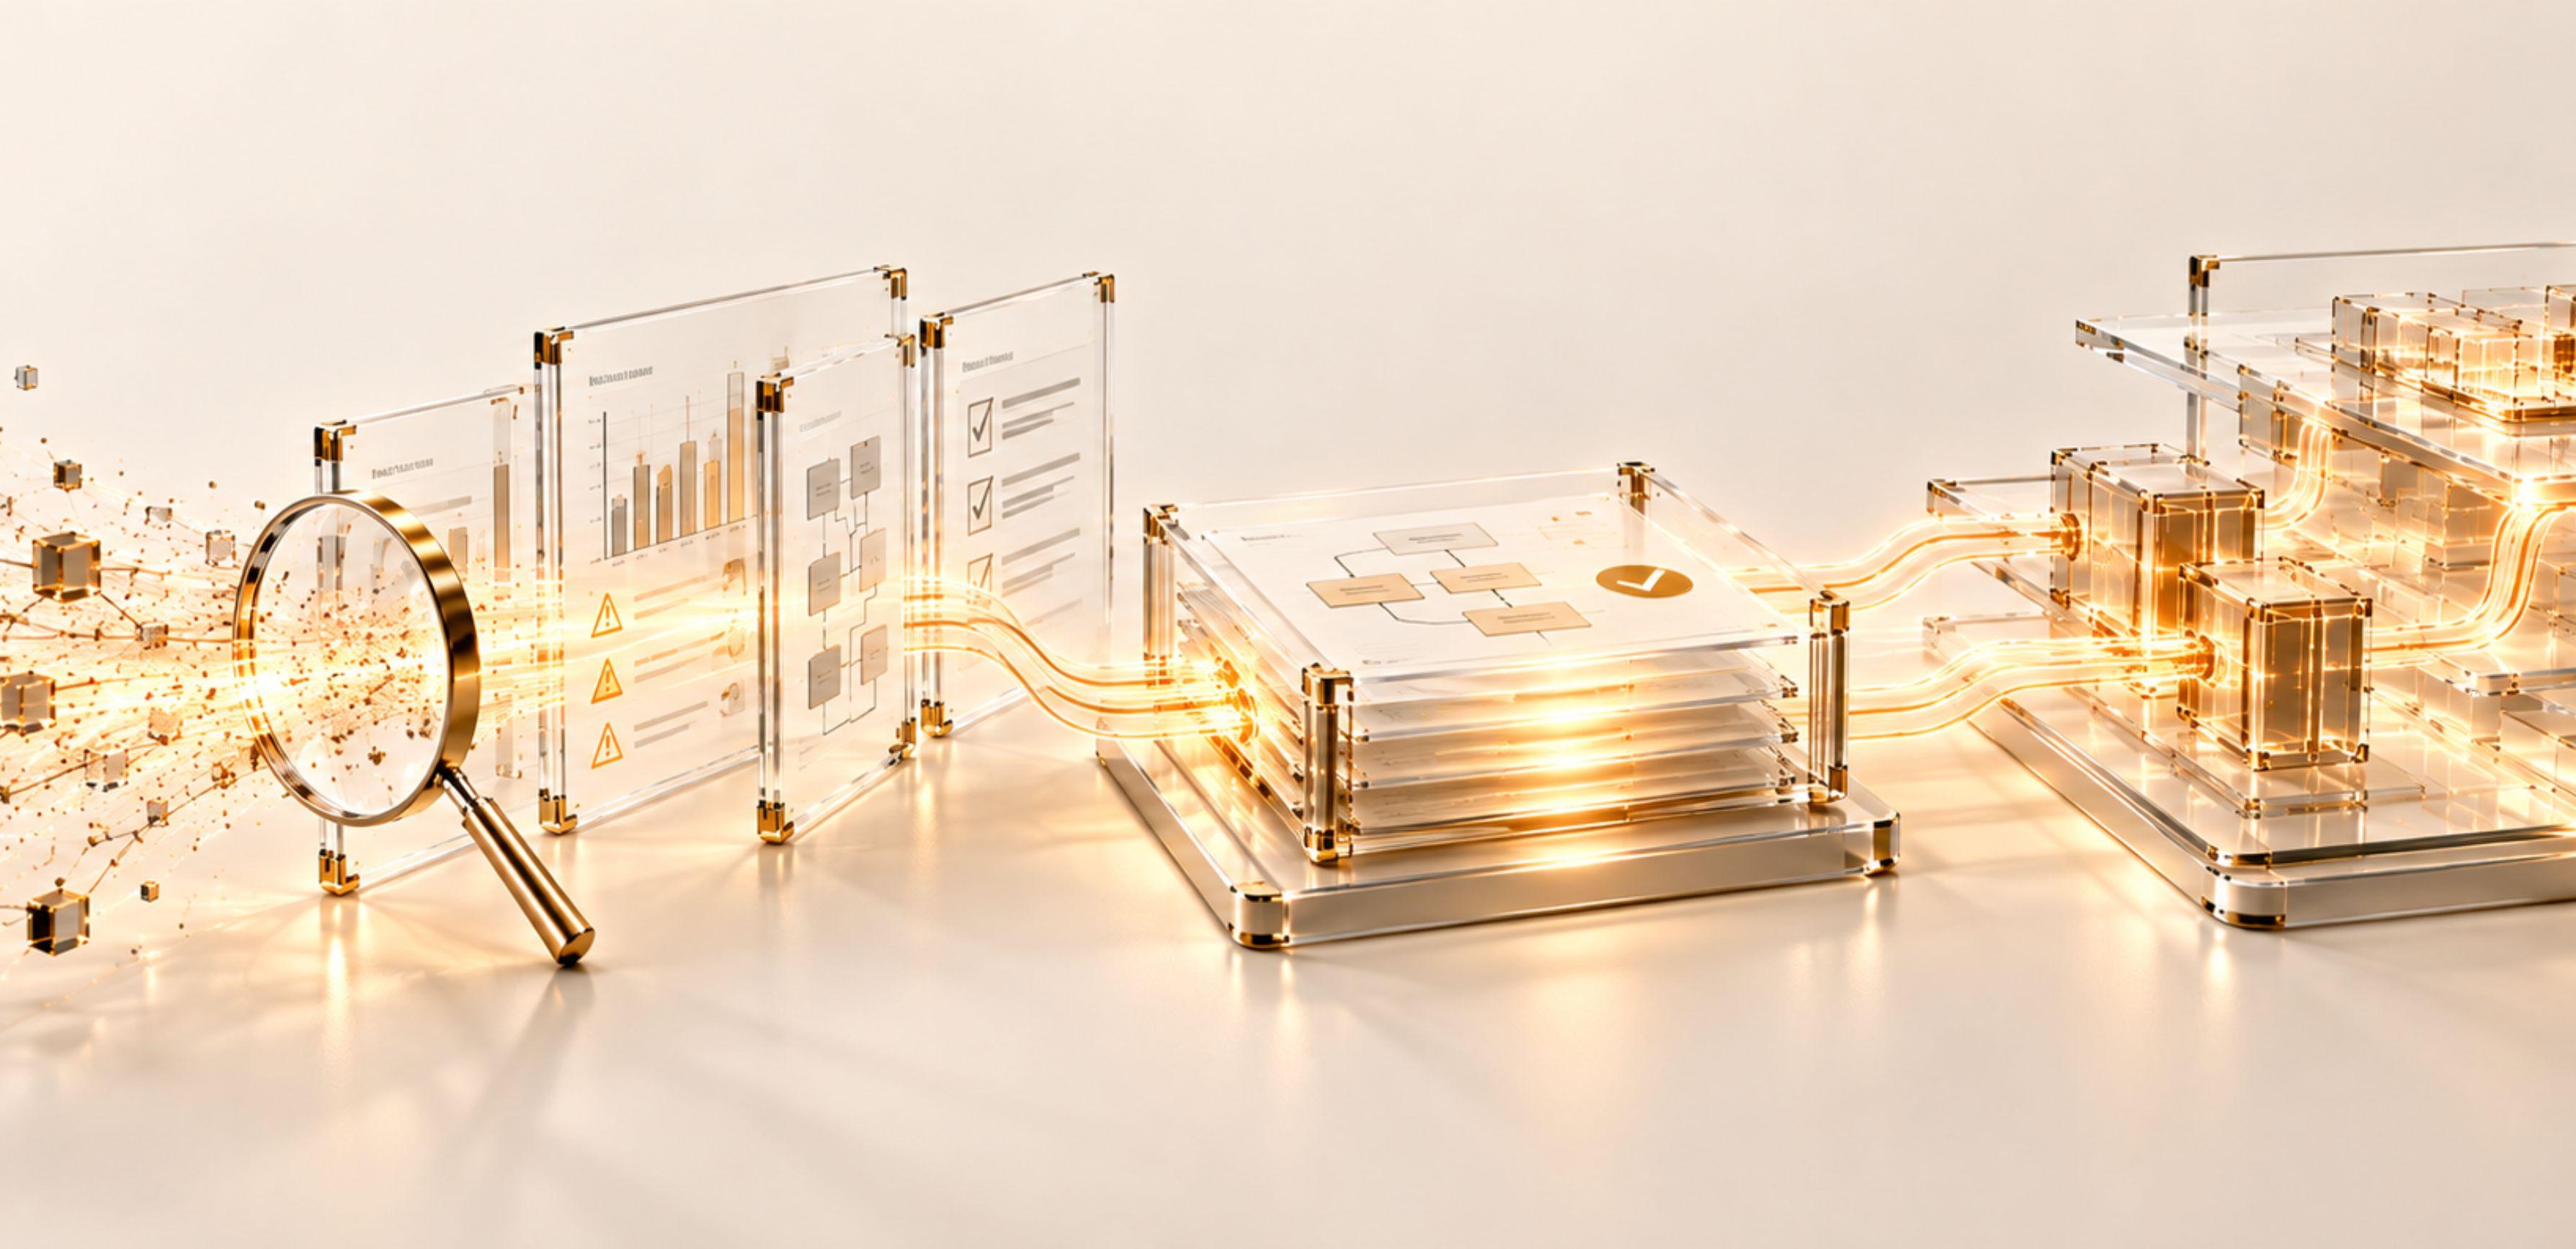
No headcount decision at all. This is a read-only audit of the current stack: CRM field hygiene, integration inventory, routing and handoff latency, forecast accuracy history. The output is a leak ledger: a ranked list of where revenue is being lost to broken process versus broken engineering versus missing headcount. Without this layer, every hire below is a guess.
Owns field taxonomy, stage definitions, native CRM automation (validation rules, assignment rules, out-of-box workflow builders), and reporting logic. Works inside vendor-supported configuration: Salesforce Flow, HubSpot Workflows, native Gong or Outreach settings. Data contract: consumes clean-enough data from existing sources; does not build new integrations between systems.
Owns cross-system orchestration: API-level integrations, event-driven triggers, sync jobs between CRM, marketing automation, product telemetry, and CS platforms. Builds and monitors the systems that RevOps configuration alone can't produce: lead routing that fires on a webhook within seconds, handoff logic that checks multiple fields across two objects before creating a task. Data contract: publishes and subscribes to defined events (lead.created, opp.stage_changed, usage.threshold_crossed) with a documented schema other systems can rely on.
Owns product-adjacent instrumentation and experimentation: activation event tracking, in-product nudges, self-serve conversion logic. Overlaps with GTM Engineering at the handoff between product usage signals and sales/CS systems, but should not own the revenue-critical sync jobs themselves: only the signals that feed them.
Build sequence: how to make the hire, not just the title decision
Build vs. buy: trade-offs
| Approach | Best fit | Cost of ownership | Failure risk |
|---|---|---|---|
| Native CRM / RevOps hire | Field governance, stage definitions, reporting inside one primary tool | Lower salary band; scales poorly past 3-4 integrated systems | Workarounds instead of fixes when the break is cross-system |
| iPaaS / workflow tool (Zapier, Make, Workato) run by a generalist or Growth Engineer | Simple, low-volume automations between two or three tools | Cheap to start; task-based pricing and fragile chains get expensive and brittle at scale | Silent failures: a zap disables itself and nobody notices until pipeline data is stale |
| Custom code / forward-deployed GTM engineering | Event-driven orchestration across the full revenue stack, tested on your own data | Higher upfront build cost; lower long-term maintenance once shipped at 85% and stable | Requires real ownership and monitoring discipline once live: the risk shifts from "did it break" to "did anyone notice" |
Companies underestimate the middle row. A workflow-tool chain that looked like a shortcut at Series A becomes the undocumented system a new GTM Engineer has to reverse-engineer at Series B, usually with no one left who remembers why a given zap exists. Evaluating the true cost means pricing in that eventual unwind, not just the monthly tool fee.
Running it in production
Whichever role owns a given system, production monitoring has to exist independent of that person's attention. A lead routing system needs an alert when volume drops to zero or when response time exceeds a threshold, not a dashboard someone checks when they remember. If the only monitoring is "the RevOps Manager notices in the weekly report," the system doesn't have a monitor, it has a hope.
Define what happens when the sync job that feeds a system goes down. Does a lead sit unrouted, or does it fall back to a default owner queue? Does a stale forecast get flagged as stale, or does it get presented to the board as current? A fail-safe state has to be designed in at build time: retrofitting it after the first silent outage is how trust in the system erodes.
The board doesn't need to know which API the handoff logic calls. They need one sentence: "leads are routed to the right rep within five minutes, automatically, and we get an alert if that stops happening." If the person who owns the system can't reduce it to that sentence, the system is probably more fragile, or more ad hoc, than the org chart suggests. This is also the test for whether the right role owns it: a RevOps Manager can usually explain a reporting process cleanly; explaining a cross-system trigger chain clearly is a sign the engineering layer is genuinely built, not improvised.
Where this fits in the system
This decision tree is upstream of every system on the VANDFORT systems page. Speed-to-Lead and Handoff Orchestrator specifically live at Layer 2: they are cross-system orchestration problems, not native CRM configuration problems, which is why companies that try to build them with a RevOps generalist alone tend to stall at the workaround stage described earlier. Forecast Assistant and Pipeline Hygiene Sentinel depend on Layer 1 being solid first: clean stage definitions and field discipline are the data contract those systems consume.
VANDFORT's model exists for the gap this article is really about: the period between diagnosing that a Layer 2 system is missing and having the internal headcount, budget, or conviction to hire a full-time GTM Engineer for it. Alejandro Lugo and Mauricio Varela built VANDFORT as forward-deployed engineers: they build the system inside your stack, on your own data, and it has to work at 85% before it ships. Read more about the two of them at vandfort.com/about. If you're trying to figure out whether your gap is a hire, a build, or neither yet, the Revenue Leak Report is the read-only, three-week version of the diagnosis in step one above: done for you, before you commit to a headcount line.