You have lived this, maybe under a different name. A vendor embeds an engineer with your RevOps team. They get read access to Salesforce, HubSpot, your data warehouse. They start mapping objects: Lead, Opportunity, Account, the sync job between your MAP and CRM, the triggers that fire on stage change. Three months in, they are still mapping. Six months in, they have write access to two systems and a growing list of "phase two" items. Twelve months in, you are paying for a full-time engineer who reports into a vendor's org chart, and nobody can tell you what shipped, what it costs to run, or what happens if that specific person leaves. The engagement never had an edge. It just had a start date.
That is not a people problem or a tools problem. It is what happens when you borrow the forward-deployed engineering model without borrowing the constraint that makes it work: a fixed-scope diagnosis before anyone writes a line of orchestration logic.
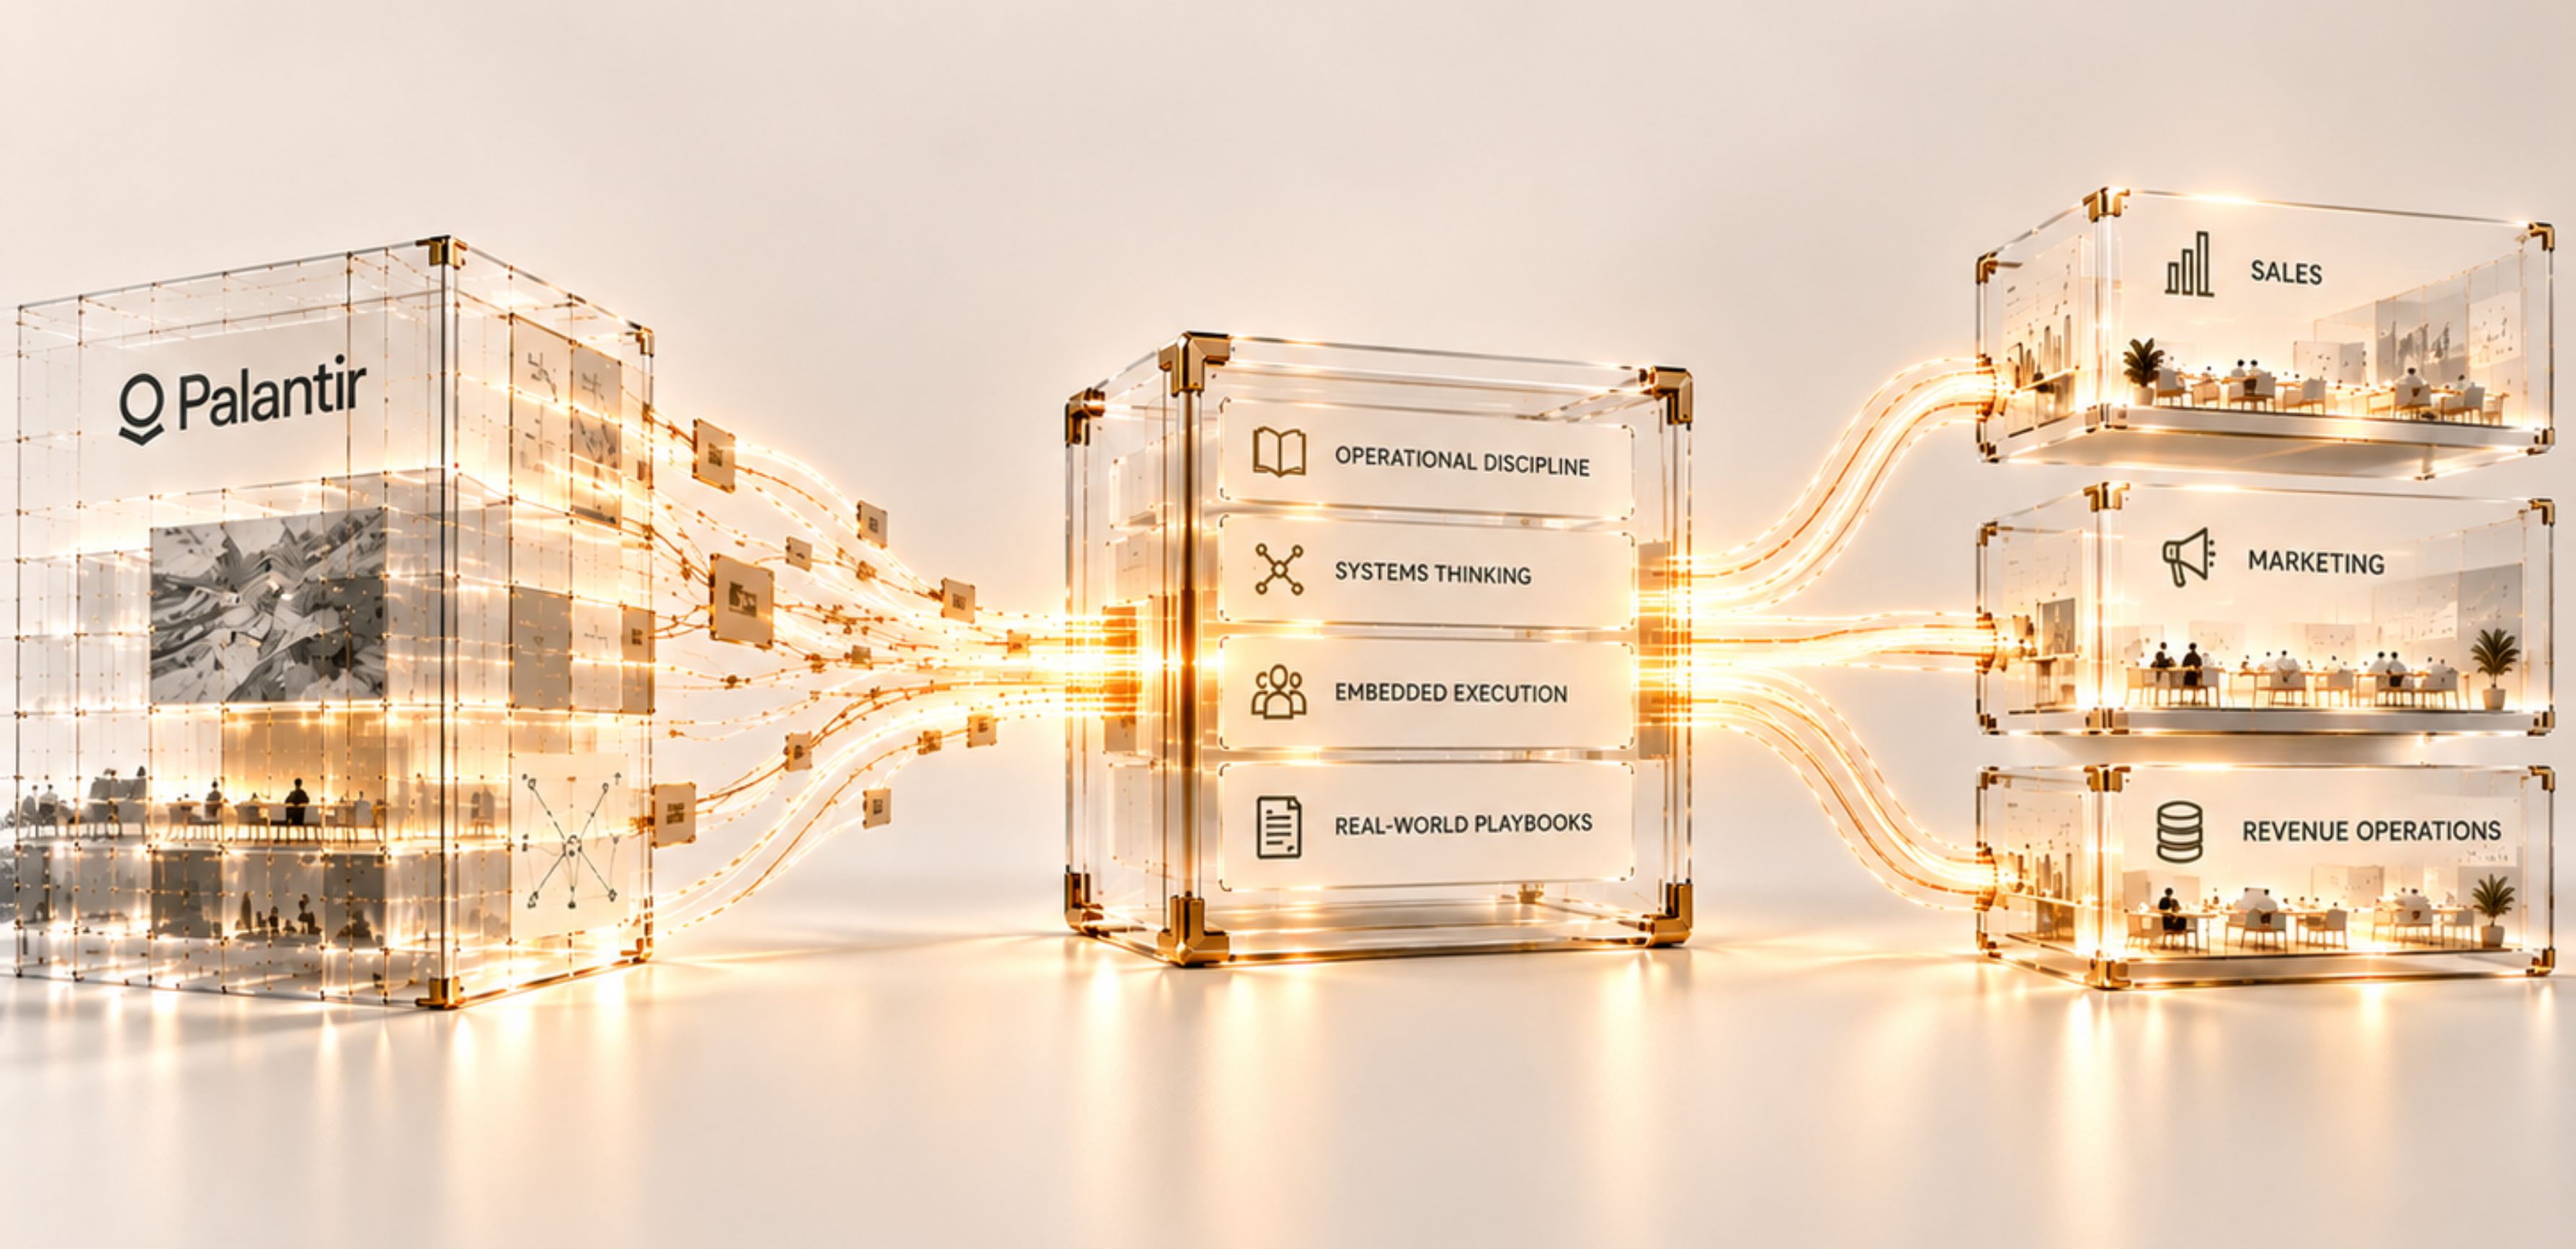
Palantir built the FDE model to solve a specific problem: software that has to work inside an existing, messy, high-stakes operational environment (a battlefield, a supply chain, a hospital system) cannot be specced from a distance. Someone has to sit inside the environment, see the actual data, and build against what is really there instead of what the requirements doc says is there. Revenue teams have the same problem. Your lead routing logic, your handoff triggers, your forecast roll-up: none of it can be designed correctly from a kickoff call and a discovery deck. Someone has to look at your actual Salesforce instance, your actual sync jobs, your actual field-level mess, before they can build anything that survives contact with production.
That part of the playbook transfers cleanly. What does not transfer automatically is the discipline that keeps an embedded engineer from becoming a permanent, unaccountable line item. Palantir's model works because the forward-deployed engineer operates against a defined mission with defined success criteria, not because embedding itself is magic. Strip out the fixed scope and "forward-deployed" is just a fancier word for staff augmentation with better branding.
Where it breaks
The failure modes below are specific, not generic "consulting goes wrong" complaints. Each one has a concrete signature in your stack: a field that never got a definition, a trigger nobody owns, a sync job that silently started dropping records.
The embedded engineer becomes a headcount line with no exit condition
This is the most common failure, and it is structural, not personal. Without a written diagnosis (specific objects, specific failure points, specific systems to build), an embedded engineer's job naturally expands to fill the calendar. They get pulled into ad hoc requests: "can you also fix the lead scoring field," "can you also look at why forecast roll-up is off." Every one of those requests is legitimate. None of them was scoped. Eighteen months later you have paid for a person, not a system, and the person's knowledge (which fields matter, which triggers are load-bearing, why the sync job runs in that order) lives in their head, not in a runbook.
Read access forever, write access never
The FDE model's "read access first" principle is correct: you should not let anyone write to production before they understand what is actually happening in Opportunity.StageName transitions or the Contact-to-Lead conversion logic. But some vendors stop there. They stay in observation mode indefinitely, producing dashboards and recommendations, because moving to write access requires them to commit to a testable outcome. Read-only forever is not caution. It is a way to avoid the moment where a system either works or it does not.
Software that does not stay because it was never meant to leave with anyone but the engineer
Palantir's stated goal is that forward-deployed engineers eventually leave software behind that the client can run independently. In GTM engagements, this is where most vendors quietly fail. The routing logic gets built inside a personal Zapier account, or a custom Apex trigger with no comments, or a workflow in a tool the client doesn't have an enterprise license for. There is no data contract documenting what fields the logic reads, what events it listens for, what it writes back. When the engagement ends, the "system" is actually a person's undocumented judgment encoded loosely in a tool. It breaks the first time a field gets renamed.
No fixed-scope diagnosis before build begins
This is the root cause behind the first three. Unbounded consulting happens when discovery and build collapse into the same open-ended phase. There is no moment where someone says: here is the leak ledger, here are the specific systems that close it, here is what "done" looks like for each one. Without that moment, scope has nowhere to stop expanding, because every new finding during the engagement looks like a justification for more work rather than a candidate for a future, separately scoped system.
Ownership of the system of record never transfers
Even when software does get built and does stay, ownership frequently does not. The vendor remains the only party who can safely modify the trigger or the sync job, which means "the software stayed" is technically true and operationally false. You are still dependent on the vendor for every change, which is the same lock-in as a headcount line, just wearing different clothes.
Reference architecture
The layers below are the ones a forward-deployed engagement actually has to touch in a B2B SaaS revenue stack, in order. The design principle that keeps this from becoming unbounded consulting is that each layer has an explicit data contract with the one above and below it, meaning any engineer, including one who was never in the room, can read the contract and know what a layer expects and produces.
Product usage events, form fills, intent data, call transcripts, support tickets. Example tools: Segment, a product analytics pipeline, Clearbit or similar enrichment feeds, Gong or Chorus call data. Contract with the layer above: every source event carries a stable identifier (account domain, contact email, or a warehouse-assigned entity ID) and a timestamp. No event should be consumable downstream without one.
Deduplication logic, entity resolution across systems, field standardization. Example tools: a reverse ETL layer, a warehouse (Snowflake, BigQuery) doing the matching, or native CRM dedup rules for simpler cases. Contract: every downstream system receives one canonical record per account and per contact, with a documented matching rule, not five overlapping "Account" records with different spellings of the same company.
The actual routing, scoring, and triggering rules: speed-to-lead assignment, handoff conditions, signal thresholds for outbound. Example tools: an iPaaS layer (Workato, Tray), native CRM flow builders, or purpose-built code where logic is too conditional for point-and-click tools. Contract: every rule fires off a named, versioned event (lead.created, stage.changed, signal.detected) and writes its output to a specific field with a documented definition, not a free-text note.
Salesforce or HubSpot as the object model of truth for Account, Opportunity, and Contact state. Contract: fields written by orchestration logic are owned by that logic. No manual overwrite without a corresponding change to the rule, and every automated write is attributable to a specific job or trigger, visible in field history.
Where the system actually acts: an SDR gets an alert within minutes, a rep sees a pipeline hygiene flag, a CSM gets a churn signal, a board report auto-generates. Example tools: Slack alerts, in-CRM tasks, an AI agent drafting outbound copy. Contract: every activation references back to the specific rule and record that triggered it, so a rep or leader can trace "why did I get this" to a specific event, not a black box.
// example data contract, Layer 3 -> Layer 4
event: lead.speed_to_lead_breach
fires_when: Lead.CreatedDate + 5min elapsed AND Lead.Status = 'New' AND Lead.OwnerAssignedAt IS NULL
writes_to: Lead.SLA_Breach_Flag__c (boolean), Lead.SLA_Breach_Timestamp__c
owned_by: orchestration layer, job "speed-to-lead-monitor"
downstream_consumer: Layer 5 Slack alert to Lead.Owner + RevOps channel
Build sequence
Build vs. buy: trade-offs
| Approach | Fit | Cost of ownership | Failure risk |
|---|---|---|---|
| Native CRM automation (flows, workflows) | Good for simple, single-object logic: one trigger, one field update | Low upfront, rises fast as conditional logic multiplies across objects | Silent breakage when fields get renamed or flow order conflicts with other automations |
| iPaaS / workflow tool (Workato, Tray, Zapier-class) | Good for multi-system orchestration where logic is moderately complex but doesn't need custom scoring or NLP | Moderate: licensing plus a maintainer who understands the whole flow graph, not just one step | Fragile to API changes in connected tools; failures often go unnoticed without explicit monitoring |
| Custom code / embedded engineering (forward-deployed) | Best fit when logic needs to reason over messy, conditional, real data: scoring, agent-driven responses, cross-object judgment | Higher upfront, but lower long-term if ownership and documentation actually transfer | Highest risk when scope is unbounded; lowest risk when scoped, tested against real data, and handed off with a runbook |
The honest answer for most revenue teams is a mix: native automation for the trivial cases, an iPaaS layer for orchestration across two or three systems, and embedded engineering only for the systems where judgment under messy conditions actually matters: speed-to-lead routing under real load, churn signal detection across noisy usage data, forecast logic that has to reconcile conflicting rep and manager inputs.
Running it in production
Every orchestration rule needs a visible failure signal, not a silent one. If the speed-to-lead job stops firing because a field got renamed in a CRM release, the first person to notice should not be a rep three weeks later wondering why pipeline dried up. Build a daily check on event volume: if lead.speed_to_lead_breach events drop to zero or spike unexpectedly, that is the alert, before anyone looks at conversion numbers.
Design for the sync job going down, not just for it working. If the identity resolution layer can't match a new lead to an existing account, the system should route to a human review queue, not silently create a duplicate or silently drop the record. Every automated layer needs an explicit "I don't know" path, a fallback that degrades gracefully instead of failing invisibly.
A CRO does not need to see the trigger logic. They need one sentence: "leads are routed within 5 minutes based on territory and score, and here is the weekly rate of on-time routing." Every system needs a leadership-facing summary that maps directly back to the underlying data contract, so the explanation doesn't drift from what the system actually does. This is the same discipline behind a credible proof narrative: it has to trace back to the real mechanism, not a story about it.
Where this fits in the system
The forward-deployed discipline described here (read access first, fixed-scope diagnosis, build against real data, ship at a working threshold, hand off ownership) is the operating model behind every one of VANDFORT's nine systems, not a separate methodology bolted onto them. It is most visible in the two GTM Operations systems most exposed to the failure modes above: the Speed-to-Lead system, where an undocumented, unowned routing rule is exactly the kind of software that "stays" in name only, and the Handoff Orchestrator, which exists precisely because handoff logic between marketing, SDR, and AE teams is the layer most often left as tribal knowledge instead of a documented data contract. Both are built the way this piece argues embedded engineering should work: scoped, tested on the client's own data, and shipped to a defined threshold (VANDFORT's stated bar is 85 percent) rather than left open-ended. Co-founders Alejandro Lugo and Mauricio Varela built the engagement model around this exact constraint, because the alternative is the failure mode this post opened with: an embedded engineer with no edge to the mission.