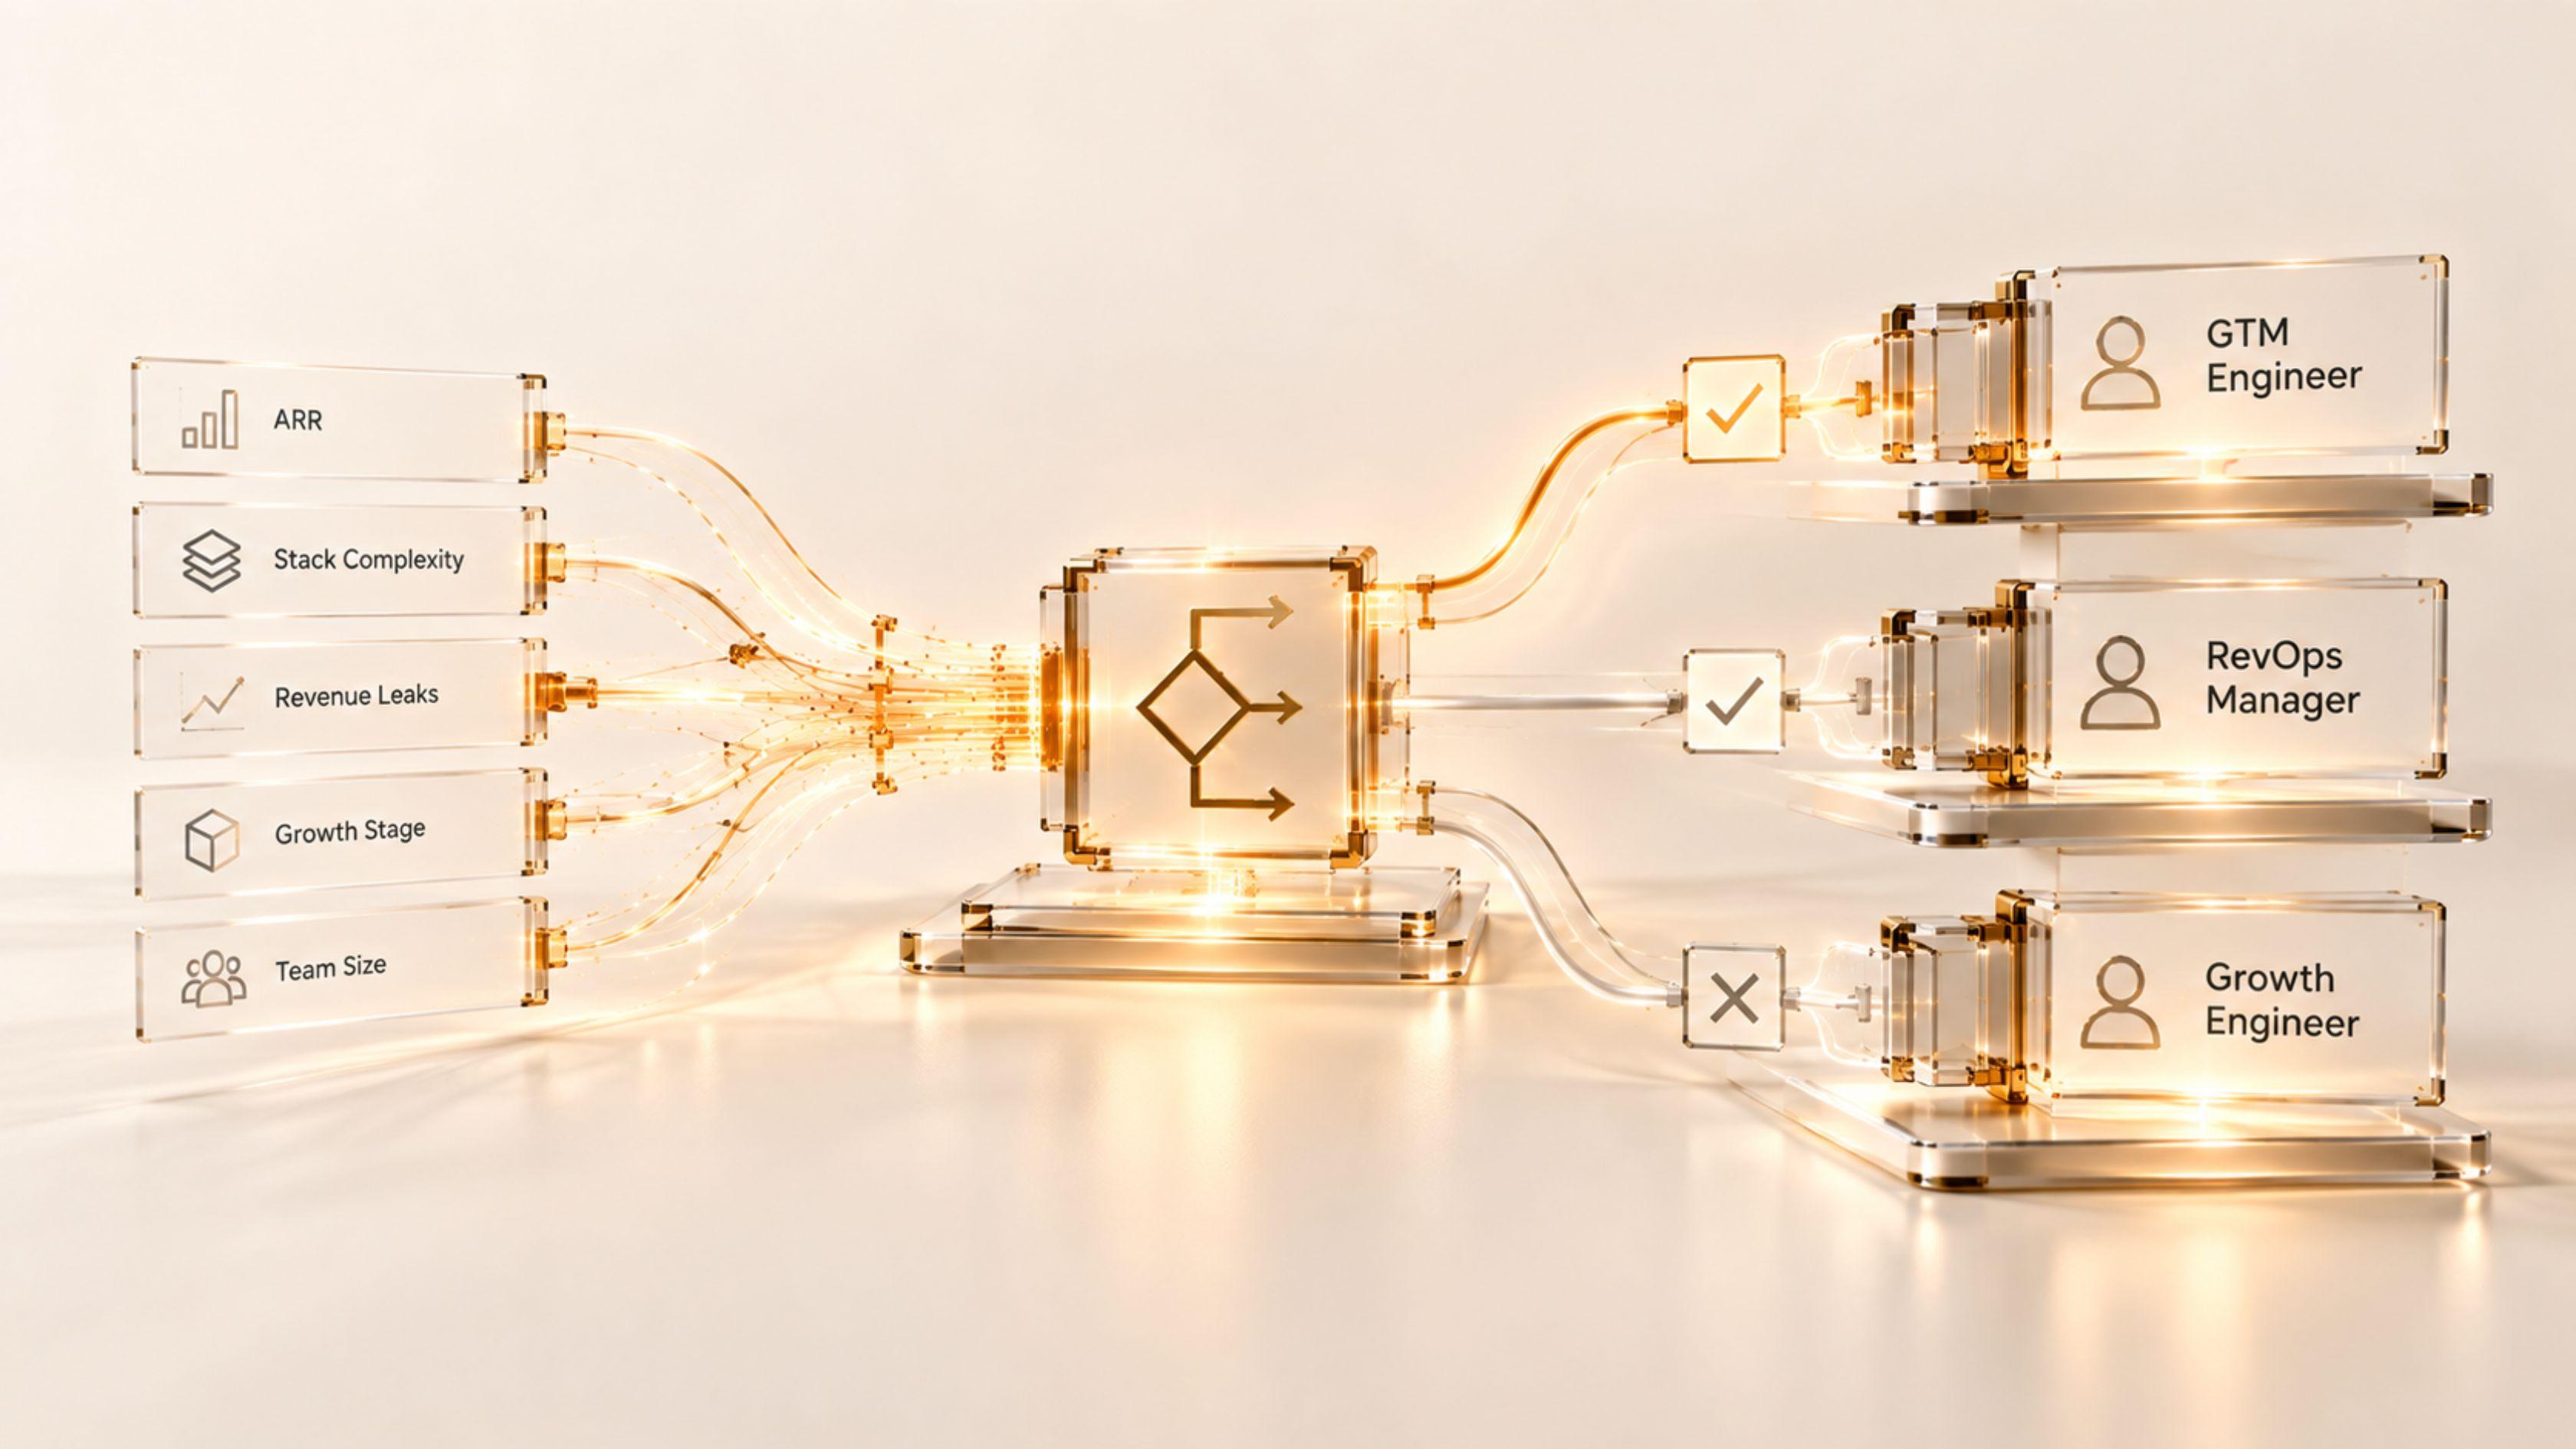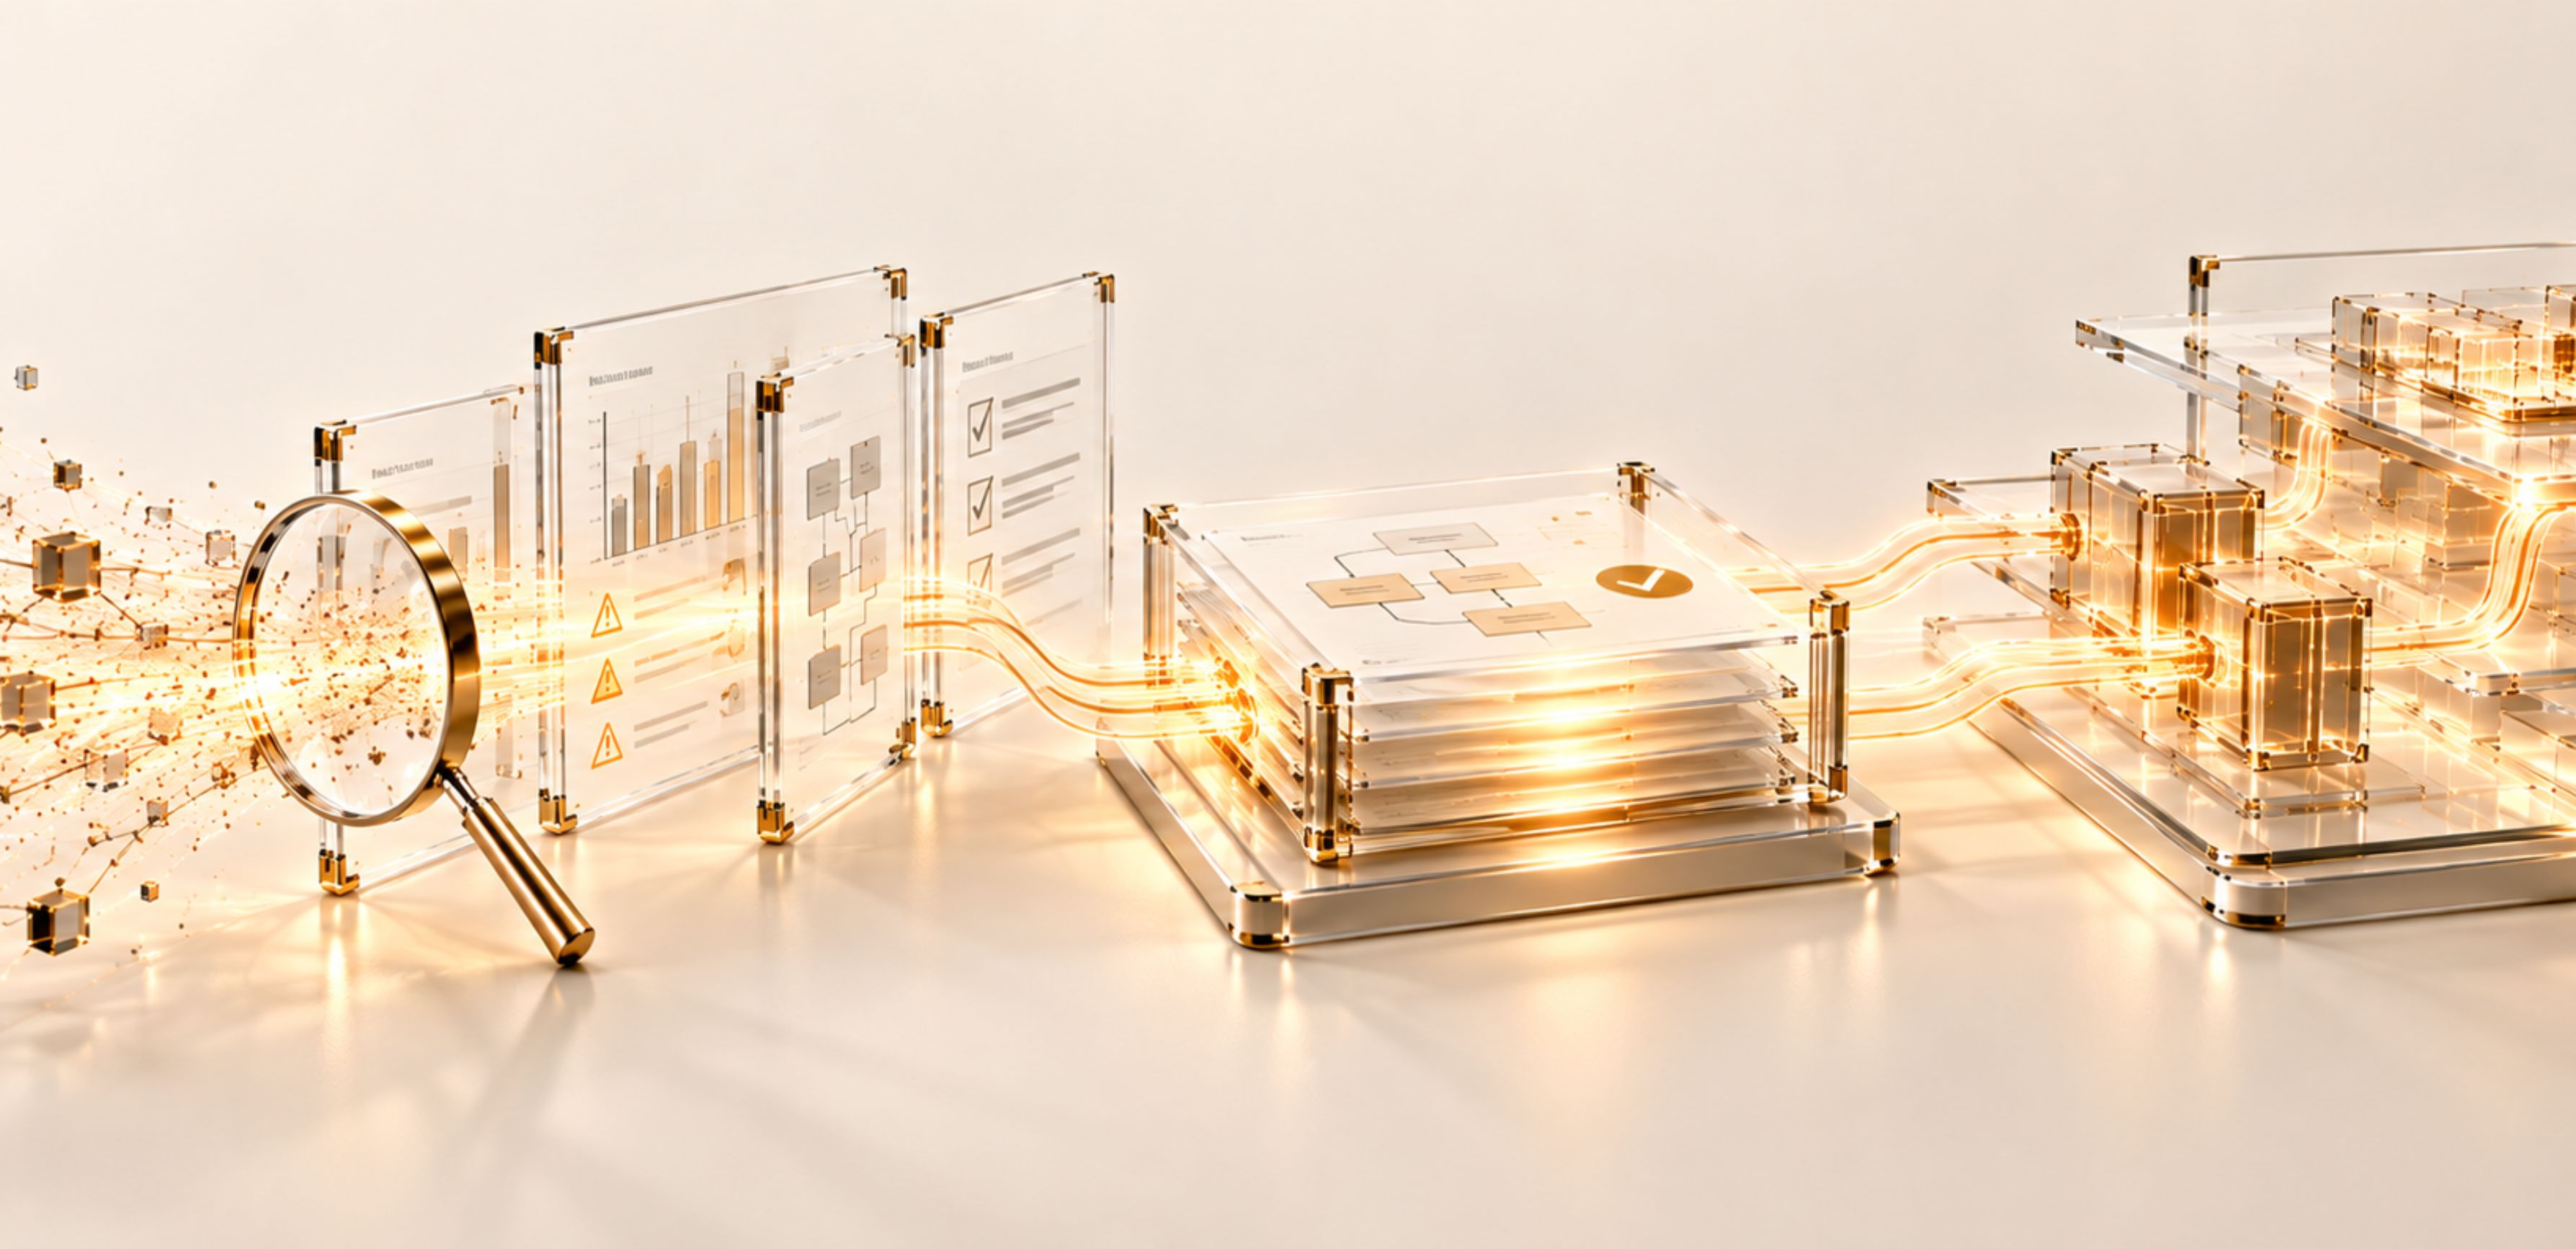
A CRO we spoke with last year had just closed a deal on a new lead routing platform. The business case was clean: reps were complaining that inbound leads sat untouched for days, marketing was pointing at sales, sales was pointing at marketing, and someone in the boardroom had read that fast response correlates with win rate. Six months and one implementation later, response time on the dashboard looked better. Pipeline conversion did not move. When we pulled the raw event log during a later audit, the actual leak was three steps downstream of routing: a handoff between SDR and AE where the opportunity record sat in a status field nobody owned, waiting for a manual Slack message that happened, on average, a day and a half after the routing tool had already done its job perfectly. They had bought a fix for a problem they did not have, and left the actual leak untouched.
This is not a story about a bad tool. The routing platform worked as designed. It's a story about diagnosing at the wrong layer of the system: treating a visible symptom as the root cause because nobody had traced the object (the lead, then the opportunity) through its full lifecycle before writing the purchase order.
This is a systems problem, not a people problem or a tool problem, because the failure mode is structural: revenue teams buy against a symptom they can see (slow response, missed forecast, churn spikes) without first tracing which object, field, or handoff in the pipeline is actually breaking. A tool bought against a symptom will improve the symptom's proxy metric and leave the underlying leak exactly where it was, because the leak usually lives one or two hops away from where the pain is felt. Diagnosing before building means instrumenting the full path (fields, events, triggers, sync jobs) and finding where the object actually stalls, before deciding whether the fix is a configuration change, a workflow rebuild, or a genuinely new system. Our own intake process runs on this logic: before we scope any of VANDFORT's nine systems for a client, the engagement starts with a Revenue Leak Report, a three-week, read-only diagnostic, precisely because we've seen what happens when a team skips that step. The pattern below is drawn from anonymized findings across those audits: not any single client, but the leak ledger patterns that repeat often enough to be structural rather than anecdotal.
Where it breaks
1. Symptom-matched purchasing
The most common anti-pattern: a tool is selected because its name matches the symptom. Slow lead response gets a routing tool. Missed forecasts get a forecasting tool. Churn gets a health-score platform. But the symptom is a lagging indicator sitting downstream of several objects (lead.created, lead.assigned, lead.status, opportunity.stage_changed) and the actual break is frequently upstream or in a handoff between two systems, not inside the system the new tool touches.
2. Tool sprawl over a shared broken object
Teams that have already tried to fix a leak once often layer a second and third tool on top of the same underlying field instead of fixing it. We regularly find three or four automations writing to the same lead_status or account_stage field with conflicting logic (one from marketing automation, one from a CRM workflow rule, one from an outbound sequencing tool) because each new purchase was scoped without checking who else already owned that field.
3. Anecdote-driven roadmaps
RevOps teams under pressure to "do something" often prioritize fixes based on which rep complained loudest this quarter, not on which stage transition has the largest volume-weighted drop-off. A single AE's story about a lost deal can outweigh a leak affecting forty other accounts simply because it's the leak leadership heard about in the QBR.
4. No pre-purchase baseline
Without a baseline captured before a tool goes live, there is no way to attribute movement in the number to the purchase versus seasonality, rep headcount changes, or a pricing update that shipped the same quarter. We've seen teams unable to answer, six months after a purchase, whether the tool did anything at all, because nobody exported the event-level baseline before implementation.
5. Demo-driven selection
Vendor demos are built to look good on clean, small datasets. The failure surfaces later, against the client's actual data volume, duplicate rate, and field inconsistency. A tool selected on a 20-record demo frequently breaks the first time it hits a CRM with 40,000 duplicate contact records and a stage taxonomy that's been redefined four times by four different RevOps leads.
Reference architecture
The diagnostic itself follows a layered architecture, the same one we use to scope which of the nine systems a revenue engine actually needs. Each layer is audited independently, with its own data contract to the layer above it, before any fix (tool, workflow, or system) is proposed.
Raw signal: CRM (Salesforce, HubSpot), marketing automation (Marketo, HubSpot), product usage events, support/ticketing (Zendesk, Intercom), call intelligence (Gong, Chorus). Contract to the next layer: every object (lead, account, opportunity, ticket) must carry a stable external ID and a timestamped event log, not just a current-state field.
Account and contact matching, dedup logic, field completeness checks. Components: matching rules keyed on domain and normalized company name, null-rate audits on required fields (industry, ICP tier, owner). Contract to the next layer: one canonical account/contact record per real-world entity, with a documented match confidence score, before any orchestration logic reads from it.
Routing rules, SLA triggers, sync jobs between systems (iPaaS tools like Workato or Zapier, or native CRM automation). Contract to the next layer: every trigger fires against a defined event, writes to a single owned field, and logs a timestamp: no silent writes, no orphaned automations with no clear owner.
CRM as the source of truth for stage, forecast category, and ownership. Contract to the next layer: stage definitions are documented and enforced (not just named), and every stage transition is logged as an event, not overwritten in place.
The humans and AI agents acting on the data: reps, CS managers, and the systems in GTM Operations, Sales Operations, CS Operations, and Revenue Intelligence. Contract: this layer only acts on data that has already passed through layers 1-4 clean; it does not compensate for upstream breaks with manual workarounds.
Build sequence
Build vs. buy: trade-offs
Once a leak is diagnosed and classified, the question shifts from "which tool" to "which architecture fits this specific fix." The three common paths carry different cost-of-ownership and failure profiles.
| Approach | Best fit | Cost of ownership | Failure risk |
|---|---|---|---|
| Native CRM workflow / automation | Single-field or single-trigger fixes fully contained inside one system (e.g., a stage-change alert, a field validation rule) | Low: no new license, maintained by existing CRM admin | Low for simple logic; breaks silently as rule count grows and rules start conflicting |
| iPaaS / workflow tool (e.g., Workato, Zapier, Make) | Fixes spanning two or more systems with a clear, stable data contract (CRM to support tool, marketing automation to CRM) | Medium: new license, ongoing maintenance as source schemas change | Medium: sync jobs fail silently on schema drift; needs monitoring and retry logic |
| Custom code or AI agent | Fixes requiring judgment, unstructured data, or logic too complex for point-and-click workflows (signal scoring, churn pattern detection, forecast narrative generation) | Higher upfront, lower long-term if built and owned correctly, with no per-seat licensing drag | Highest if built without testing against the client's own data first; lowest failure risk of the three once validated at production volume |
The mistake we see most often is reaching for the third option (custom code or an agent) before confirming the leak isn't actually a first-option fix: a missing validation rule or an unowned field that a native workflow could resolve in an afternoon.
Running it in production
Once a fix ships, the leak ledger doesn't get archived; it becomes the monitoring baseline. Track the same conversion-rate and time-in-stage metrics weekly against the pre-fix numbers, not just a generic dashboard KPI, so drift shows up before a rep notices it anecdotally again.
Every sync job and trigger built to fix a leak needs an explicit failure state: what happens when the source field is null, when the API rate-limits, when two automations try to write the same field at once. Design the fallback (queue, alert, human review) before go-live, not after the first silent failure is discovered three weeks later.
Leadership doesn't need the trigger logic; they need the before-and-after on the leak ledger: this stage converted at X, we found the break was in this field or handoff, we fixed it, and it now converts at Y, worth Z in recovered pipeline. That framing is also what justifies not buying the next tool until the current fix has been measured.
Where this fits in the system
The diagnostic described here is the entry point to VANDFORT's engagement model, not a separate service. A Revenue Leak Report produces the ranked leak ledger; the fixes that come out of it map directly onto specific systems rather than generic tooling. A broken handoff between SDR and AE, the pattern in our opening example, is exactly what the Handoff Orchestrator is built to close, with defined fields and SLA triggers instead of a Slack message someone forgets to send. A slow or inconsistent first-touch on inbound leads is what the Speed-to-Lead system is scoped against, once the audit confirms the break is actually at that layer and not further downstream. And when the leak is stale or ungoverned pipeline data feeding a bad forecast, that's the Pipeline Hygiene Sentinel's territory. The point of diagnosing first is that the leak ledger tells you which of the nine systems, if any, actually addresses the dollar-weighted break, instead of starting from a tool category and working backward into a justification.