Your first week goes like this. The CRO asks why the forecast moved four times last quarter. The head of sales wants lead routing fixed by Friday. Marketing says half its MQLs vanish after handoff. You open the Salesforce or HubSpot instance and find 340 custom fields on the Opportunity object, three Lifecycle Stage properties with overlapping values, 60 active workflows and flows (a dozen of them owned by people who have left) and a Zapier account on someone's personal card writing to the Account object every five minutes.
That instance is a composite rather than one company, but the pattern is familiar to anyone who has been the second RevOps hire. The first hire, often a sales ops generalist or a founder with admin rights, built whatever the quarter demanded. Nobody was wrong. Nobody was in charge of the whole either, and the CRM now reflects two years of local decisions with no global design.
The numbers explain why the job exists. Validity's State of CRM Data Management in 2025, a survey of 602 CRM users and administrators in the US, UK and Australia published in July 2025, found 76% say less than half of their CRM data is accurate and complete, and 37% say their organization has lost revenue as a direct result of poor data quality. The same study, as reported by MediaPost, found 46% have no dedicated full-time employee overseeing data quality. On the front line, Salesforce's State of Sales research, 5,500 sales professionals across 27 countries surveyed in 2024, found only 35% completely trust the accuracy of their organization's data. And Gartner research from 2020 put the average cost of poor data quality at a minimum of $12.9 million a year per organization.
This is a systems problem, not a people or tool problem. The CRM did not decay because reps are careless or because the platform is wrong. It decayed because nothing in the architecture decides who may create a field, who may write to it, which automation owns which transition, or what happens when two sources disagree. Governance is that missing layer, and it is an engineering artifact: a set of contracts enforced in configuration, not a policy document in a shared drive.
Where it breaks
Inherited instances fail in a handful of repeatable ways. Each one names objects you can find in your own org this week.
Field sprawl with no owner or definition
Custom fields accumulate because creating one is cheap and deleting one feels risky. The result is three fields for the same idea (Customer_Tier__c, Segment__c and a picklist called Size) with different fill rates and different writers. Reports built by different teams pick different fields, so the board and the sales floor see different numbers for the same segment. The tell is a field with a last-modified date inside the past month and no description, no page layout and no report that anyone can name.
Stage and status definitions that drifted
Opportunity StageName values were set up once and then extended: a "Verbal" stage added for one team, a "Pending Legal" for another, probabilities edited by hand. Lead Status and Lifecycle Stage mean different things in marketing automation and the CRM. With no written exit criteria per stage, conversion rates between stages cannot be compared across quarters, which is why the forecast moves every time someone re-reads the pipeline.
Automation with overlapping triggers
Workflow rules, Process Builder remnants, record-triggered flows, HubSpot workflows and external tools all fire on the same record update. Two of them set OwnerId, one sets Lead Status and a third-party enrichment job overwrites Industry after a rep corrected it. Nobody can predict the final state of a record after save, and nobody can say which automation caused a bad value without reading debug logs.
Unmanaged write access from the edges
Integration users with system administrator profiles, API keys in personal automation accounts, CSV imports by anyone with "Modify All" and native sync apps configured to "always overwrite." These paths bypass the validation rules you add, so fixing the UI fixes nothing. Every one of them needs an owner, a scope and a list of fields it may touch.
Duplicates and orphans that break roll-ups
Duplicate Accounts split pipeline and activity across records; Contacts without Accounts drop out of account-based reports; Opportunities without Contact Roles make attribution guesswork. These are identity problems wearing a governance costume, and they compound every other failure above.
Reference architecture
Treat governance as a layered system with a contract between each layer, the same way you would treat any data pipeline. Tools named are examples of a category, not endorsements.
Components: every path by which data enters the CRM: the UI, web forms, marketing automation sync, enrichment tools such as Clay or ZoomInfo, billing and product integrations, CSV imports and integration users.
Contract to the next layer: each entry path is registered with an owner, a dedicated integration user with a least-privilege permission set and an explicit list of fields it may create or update. Unregistered paths are closed, not tolerated.
Components: matching and duplicate rules, validation rules on required fields by stage, picklist restriction, normalization of domains, countries and job titles, using native duplicate management or a tool such as DemandTools, Plauti or Insycle.
Contract to the next layer: every Account carries a normalized domain and every Contact resolves to one Account. Records that fail validation are held for review with a reason, not saved with blanks.
Components: a single automation inventory, one record-triggered flow per object per timing (before-save and after-save) as the entry point, routing logic, and a field-ownership map that names the one writer for each governed field.
Contract to the next layer: for any governed field, exactly one automation or one human role may write it, and every automated write stamps a source and timestamp.
Components: the object model, a data dictionary for every governed field (definition, owner, allowed values, writer, downstream reports), stage definitions with exit criteria, and profiles and permission sets.
Contract to the next layer: reports and dashboards may only use fields that are in the dictionary. A field that is not in the dictionary is scheduled for deprecation, not quietly reused.
Components: dashboards, the forecast, routing, sequences, customer success health scores and any AI agent that reads or writes CRM data.
Contract: activation reads only governed fields and writes only through the orchestration layer. An agent gets the same least-privilege integration user as any other tool.
What to govern first is a priority question, and the answer is not "whatever is loudest." Rank every finding by the money it is leaking, discounted by effort. A suggested starting point, not a benchmark:
for each finding (field, flow, stage, entry path):
  exposure   = revenue that passes through the affected records per quarter
  error_rate = share of those records that are wrong or late (sample 50)
  leak       = exposure * error_rate * probability the error changes an outcome
  effort     = days to fix + days to test

  priority   = leak / effort

sequence:  days 0-30  -> stop new damage on the top 3 by priority
           days 31-60 -> repair and define (dictionary, stages, dedupe)
           days 61-90 -> enforce and hand over (permissions, monitors)
Illustrative example, with made-up round numbers: if $2M of pipeline a quarter flows through inbound leads, 20% of them are misrouted and a misroute halves the chance of conversion on, say, a quarter of those, the routing finding is leaking far more than a messy Industry picklist that feeds one dashboard. Fix routing first, even if the picklist generates more complaints.
Build sequence
Six steps across ninety days. Each ends in a test you can run before moving on.
Days 1 to 10: freeze and inventory, read-only
Pause new field creation and new automations for thirty days, with an exception path that comes through you. Then export metadata: every custom field with fill rate and last-modified date, every active automation with its trigger object and the fields it writes, every integration user with its permissions. The diagnose-before-you-build playbook covers how to run this without touching a record. Test: you can produce, for the Opportunity and Lead objects, a list of every writer of every field used in the forecast and routing.
Days 10 to 20: size the leaks and rank them
Sample fifty recent records per high-value flow (inbound routing, stage progression, closed-won handoff to customer success) and measure how many are wrong, late or orphaned. Apply the priority logic above. Test: the top three findings each have a dollar exposure, an error rate from your sample and an effort estimate the CRO has seen.
Days 20 to 30: stop new damage on the top three
Close the entry paths and fix the automations that create the highest-priority errors: move rogue integrations to dedicated integration users, restrict overwrite behavior on the fields that matter, and consolidate the flows that fight over OwnerId or stage. Test: resample the same flows after a week and show the error rate falling on new records.
Days 31 to 60: define, then repair
Write the data dictionary for governed fields and the stage definitions with exit criteria, agreed with sales and customer success leadership. Then deduplicate Accounts and Contacts, merge redundant fields into one, and backfill the survivors. Test: every dashboard used in the weekly forecast call reads only dictionary fields, and duplicate Accounts by normalized domain are near zero.
Days 61 to 80: enforce in the platform
Turn definitions into configuration: validation rules on stage entry, restricted picklists, field-level security so only the owning role or automation can edit governed fields, and a change-request path (a ticket, a sandbox, a review) for new fields and flows. Test: attempt a bad write through each entry path, UI, import, API and sync, and confirm each is rejected or routed for review.
Days 80 to 90: prove it on past cases and hand over
Replay around twenty recent real records, including leads, stage changes, merges and closed-won handoffs, through the governed configuration and compare the result with what an operator says should have happened. We hold every system to the same bar: 85 percent agreement on the client's own past cases, or it does not ship. Then publish the dictionary, the ownership map and the monitors to the revenue leadership team. Test: someone other than you can answer "who writes this field and why" from the documentation alone.
Build vs. buy: trade-offs
Governance is mostly decisions, but enforcing and monitoring it needs machinery. There are three common ways to supply it.
| Approach | Fit | Cost of ownership | Failure risk |
|---|---|---|---|
| Native CRM controls (validation rules, duplicate and matching rules, restricted picklists, field-level security, field history tracking, HubSpot property permissions) | A single CRM, one or two admins, most writes coming through the UI and a small number of integrations | Lowest. Uses licenses and admin skills already in place | Rules multiply and start to conflict; native duplicate matching is limited for messy account names; nothing tells you when a rule is being bypassed through the API |
| Data quality and workflow tools (for example Plauti, Insycle or DemandTools for dedupe and normalization; n8n or Workato for governed write paths) | Several entry paths, high record volume, a recurring duplicate problem, a RevOps team that can own scheduled jobs | Moderate. Licenses plus an owner for jobs, merge rules and exception queues | Becomes another writer with its own overwrite rules if it is not registered in the ownership map; scheduled cleanups mask the upstream path that keeps creating the problem |
| Custom monitors or agents (metadata diffing, write-path audits and anomaly checks built on the metadata and event APIs, with alerts in Slack or Teams) | Large or fast-changing orgs, many integrations, AI agents writing to the CRM, a GTM engineer on the team | Highest. Needs engineering ownership, testing and on-call | Most precise and fastest to detect drift, but a small team can end up maintaining monitoring code instead of fixing the underlying design |
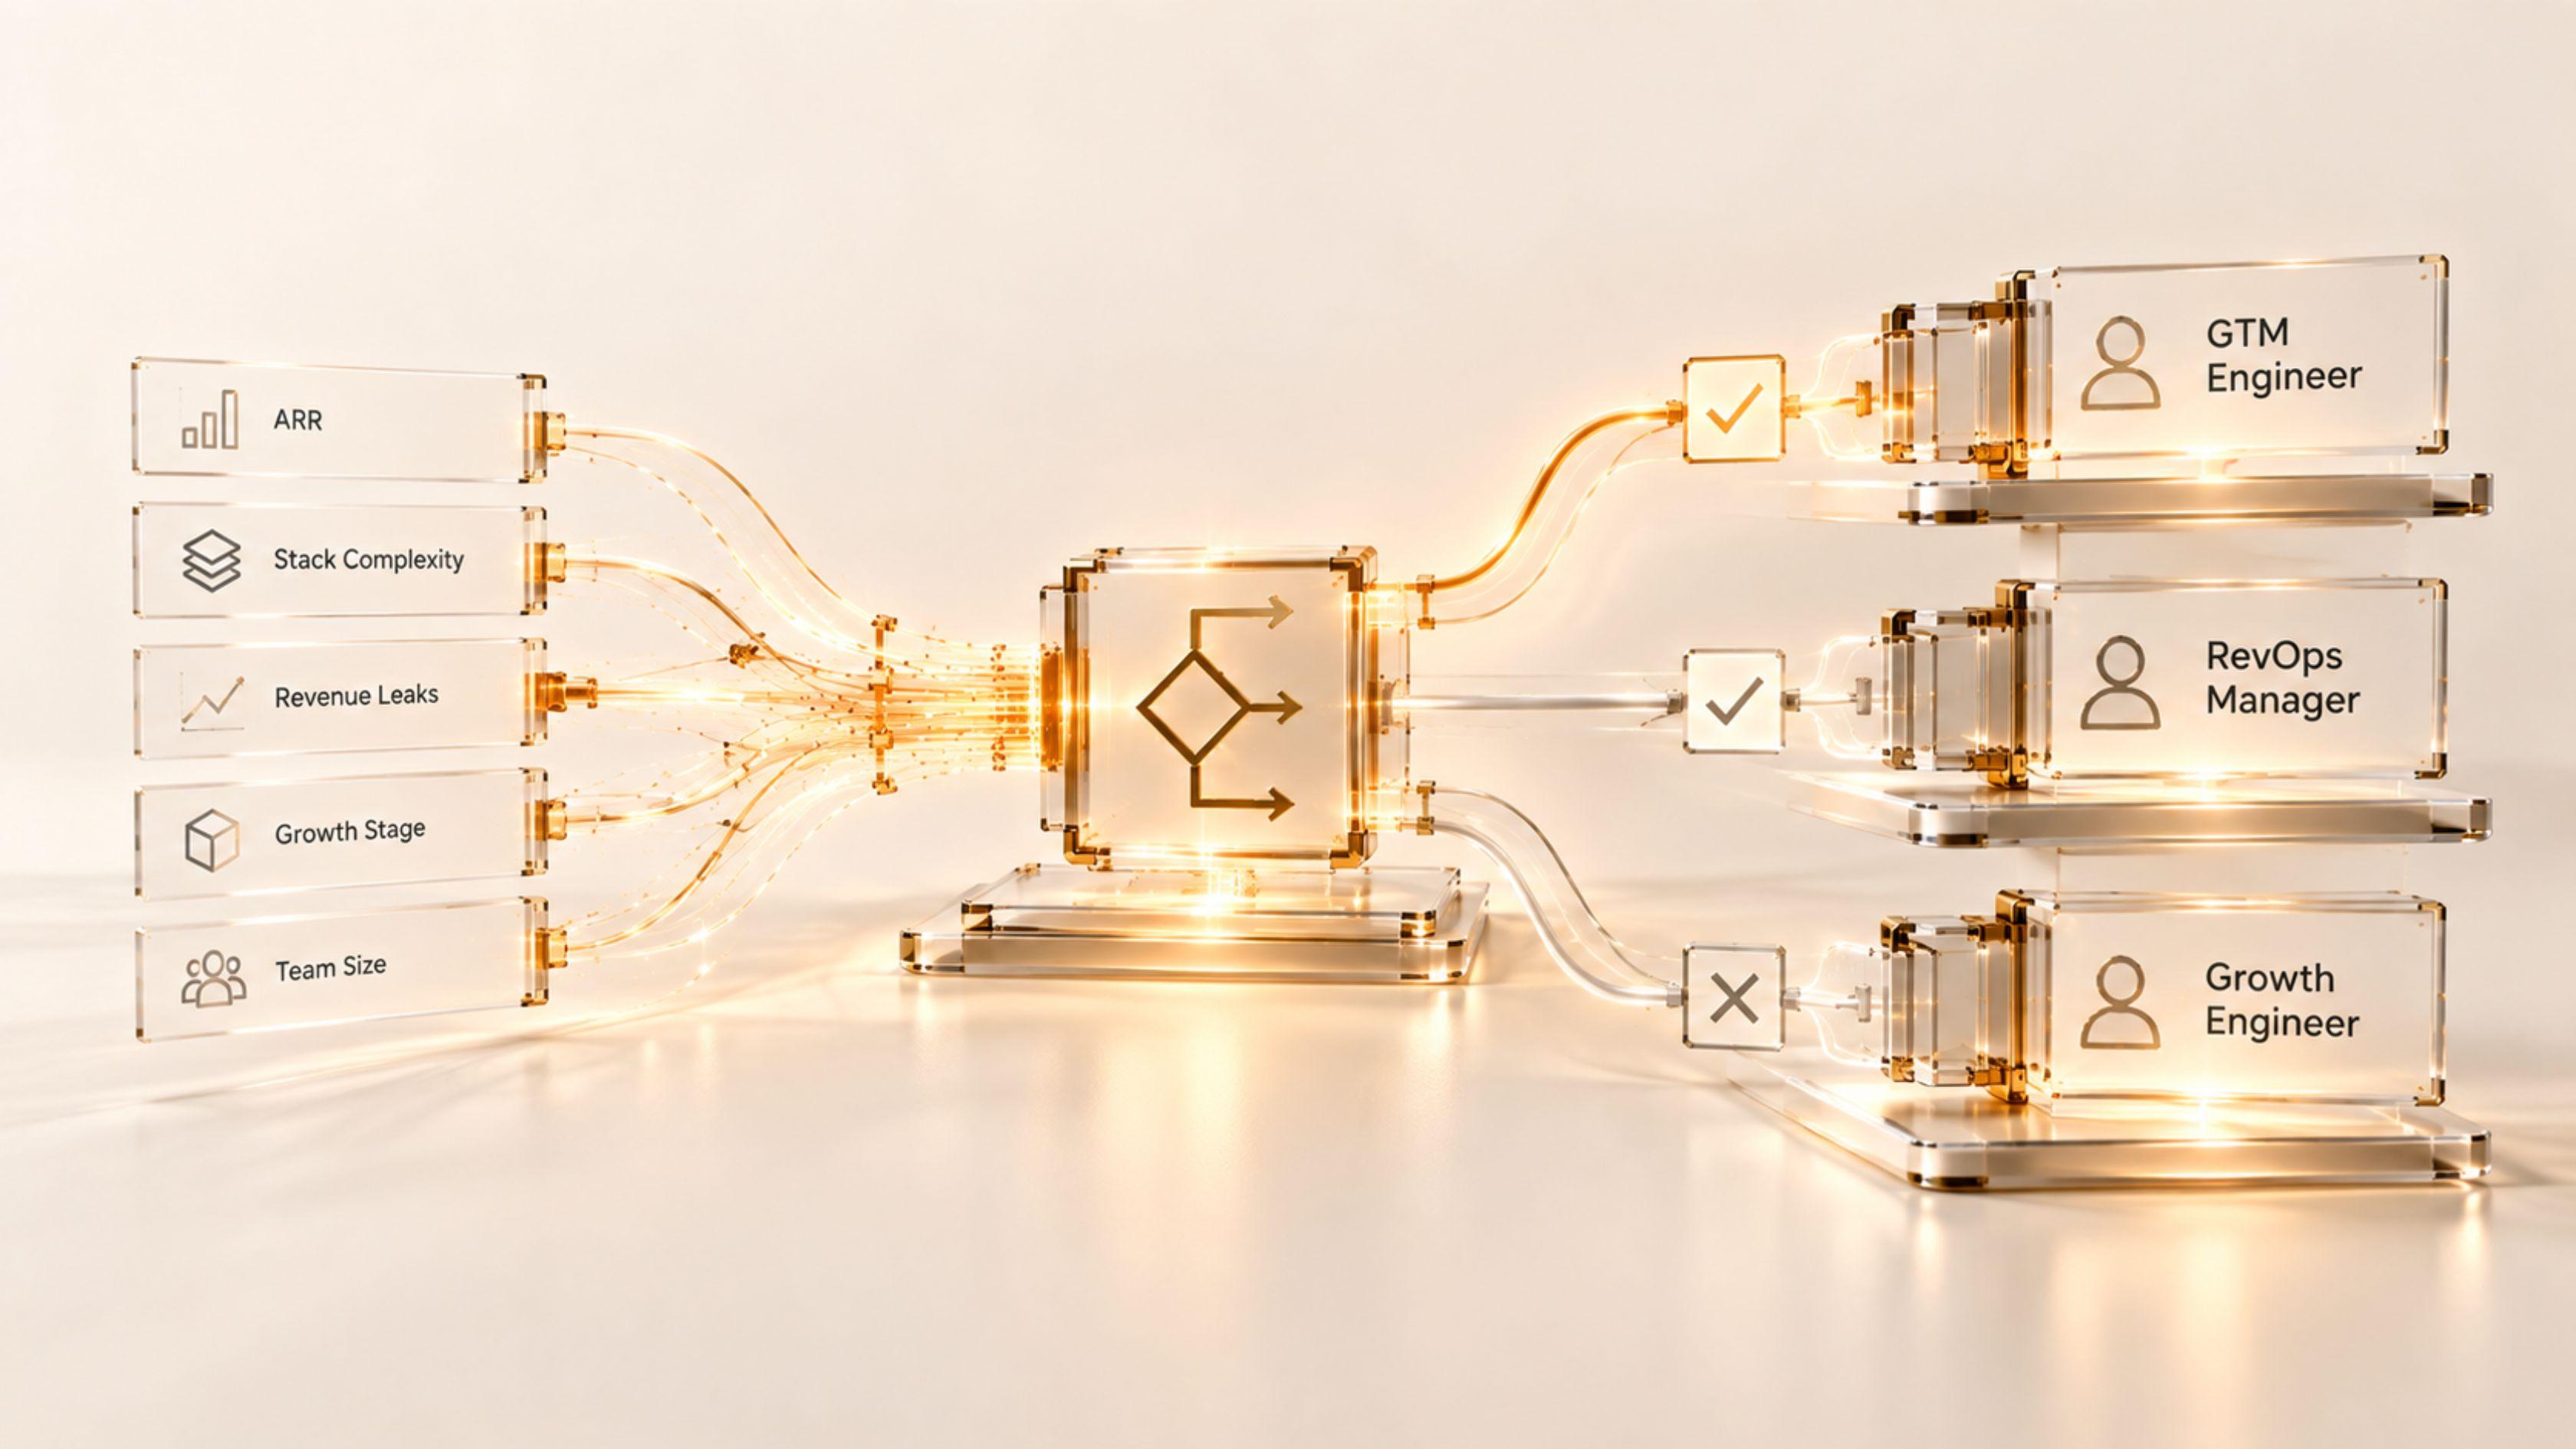
Most second hires should start native and add a tool only when a sampled error rate stays high after the entry paths are closed. Who should own the custom row is an org design question, which the GTM engineer vs. RevOps manager decision tree works through.
Running it in production
Watch a short list weekly: new custom fields and automations created outside the change path, writes to governed fields by anyone other than their owner, duplicate Accounts created per week by entry path, required-field fill rate by stage, and the sampled error rate on your top three flows. A rise in any of them usually points to one new integration or one well-meaning admin.
When a validation rule or ownership check blocks a write, the record goes to an exception queue with an owner and a response time, not to a silent failure a rep discovers at quarter end. Keep an emergency override for leadership that is logged and reviewed every week, so urgency does not quietly become the new process.
Report governance in money and trust, not in fields cleaned. Show the dollars flowing through each governed flow, the error rate before and after, and whether the forecast number changed less between weekly calls. Validity's 2025 study, as reported by MediaPost, found staff spend around 13 hours a week searching for data; time recovered is a second number leaders understand.
Where this fits in the system
Governance is the precondition for every system that reads the CRM. The Pipeline Hygiene Sentinel is governance running continuously: it checks stage exit criteria, stale close dates and missing fields against the definitions you wrote in days 31 to 60. The Forecast Assistant is only as stable as those stage definitions. Speed-to-Lead and the Handoff Orchestrator depend on a single owner for OwnerId, Lead Status and Lifecycle Stage, which is exactly what the field-ownership map enforces. The full map is on the systems page.
The order matters more than the checklist. That is the case for forward-deployed engineering in a governance rebuild: work inside the instance you inherited, size the leaks on your own records, fix one flow at a time and prove each change on real cases before it goes live.
Sources: Validity, The State of CRM Data Management in 2025 (602 CRM users and administrators, US, UK and Australia, July 2025); MediaPost reporting on the Validity study (July 11, 2025). Salesforce, State of Sales research (5,500 sales professionals, 27 countries, 2024). Gartner, data quality research (2020).